How we know it works — and where it doesn't yet.
Aufbau computes chemistry instead of retrieving it, so the honest question is: how often is it right, and how does it fail? We test the engine against a fixed set of reactions, publish the misses alongside the hits, and keep improving in the open. This page is the running account.
New: chemical nobility — some bonds have nothing left to give, and the engine has stopped offering them (patent pending).
A curated benchmark, scored without cherry-picking.
We run the shipping engine against a fixed list of 49 reactions across five classes — formation, metathesis, double-displacement, organic, and negative controls (mixtures that should not react) — and score every one, positives and negatives together. A prediction counts only if it contains the known products; a negative counts only if the engine correctly says “no reaction.”
This number went down in August 2026, and the reason is the whole point of the page. The engine had been handing back its best recombination even when it declined the reaction as too small to call — and one benchmark row, the aldol condensation of acetaldehyde, was being scored on products the engine had already refused. Aldol is near-thermoneutral and reversible; it does not proceed without base catalysis, so refusing it is the right answer. We closed the leak, the row became an honest miss, and 49/49 became 48/49.
Then it went down twice more, for a subtler reason. Two rows were being scored on the product formula, and a formula cannot tell isomers apart. In the esterification of ethanol and acetic acid the engine returns C4H8O2 as butanoic acid, not ethyl acetate. In the chlorination of ethylene it returns C2H4Cl2 as 1,1-dichloroethane, not the 1,2- that adding Cl₂ across a double bond actually gives. We taught the benchmark to compare structures, both rows failed, and 48/49 became 46/49.
The two failures were not the same failure, and that is the interesting part. For the ester, the engine preferred the wrong answer — and was right to: butanoic acid really is the more stable isomer, by exactly the margin it reported. What it lacked was a mechanism, something to forbid a product the starting materials cannot reach. For the chloride it has no preference at all: both isomers score identically, because counting one C–C, four C–H and two C–Cl is blind to where the chlorines sit. One gap needed a pathway; the other needs a term that can see substitution.
The pathway gap is now closed, and the row still fails — for a better reason. The move that built butanoic acid welded two carbon skeletons together, which ethanol and acetic acid cannot do; the rule that already refused to break a C–C bond now also refuses to form one. So the engine no longer invents that product. What it does instead is decline: esterification is bond-for-bond identical to its reactants — the same bonds on both sides — so the computed ΔH is exactly zero and there is nothing for an energy model to prefer. The ester is enumerated as a candidate; it simply cannot be chosen on energy alone. That is a sharper statement of the limit than a wrong product was, and we would rather publish the smaller number and be able to say exactly what it means.
The chloride gap is now closed too — and not the way the paragraph above predicted. We expected to need “a term that can see substitution,” some energy contribution sensitive to where the chlorines sit. That was the wrong instrument, and the reason is worth stating plainly: under bond additivity the two isomers are exactly degenerate, so there is no such term to add without abandoning additivity altogether. We were looking for a better number when the problem was not a number at all.
What the engine was actually doing is stranger. Ethylene and chlorine are small enough that it takes the mixture apart into atoms and reassembles it into whatever arrangement binds hardest — a good model of high-energy recombination, and the reason combustion comes out right. But reassembly has no memory of which atoms were bonded to which. Both isomers bind equally hard, so the answer was decided by nothing more principled than the order the candidates happened to be enumerated in. It returned 1,1- by accident, not by preference.
The mechanism has the memory the energy lacks. An addition across a double bond breaks the π bond and forms one new bond at each of the two carbons that shared it — 1,1-dichloroethane is not reachable by that move at all. So the engine now generates the product the mechanism can actually reach, and when a mechanism and a reassembly tie on energy, the mechanism wins: taking a mixture apart into free atoms is a model, not a claim about what physically happens. 46/49 became 47/49.
We then expected the last two rows to be one problem. Esterification and the aldol condensation are both near-thermoneutral, both need an acid or a base, and the engine derives its catalysts from a metal's electron configuration — so it could not express H⁺ or OH⁻ at all. One brick, two rows, we thought. That was wrong, and finding out why took reading the candidate lists rather than the summaries.
Aldol was not being declined. It was never being proposed. Aldol makes a carbon–carbon bond, and an earlier fix had taught the engine to refuse to form C–C bonds — that was how it stopped inventing butanoic acid. The refusal was right and it stays. But it meant no move in the engine could reach the aldol product at all, so no threshold, however generous, could have admitted it. We had been reading a generation failure as a scoring failure.
A base is precisely what licenses that one bond. It removes a hydrogen from the carbon next to the carbonyl — acidic only because what is left behind spreads onto the oxygen, which is why an ordinary C–H is untouchable — and the carbon left behind attacks a second molecule. The engine now generates exactly that bond and no other, and judges it the way a catalysed reaction should be judged: a catalyst removes an activation barrier, so a catalysed step has to be downhill, while everything uncatalysed still pays the full margin. Without a base the mixture stays inert, which is the correct answer rather than a limitation. 47/49 became 48/49.
Two things we did not build fell out of it. Heat the base-catalysed aldol and it goes inert again by itself — the addition turns two molecules into one, and entropy takes it back. And the relaxation cannot leak: it reaches only reactions that have both a base and a carbonyl with a neighbouring hydrogen, so every negative control stays inert with acid or base present at every temperature. That is a test in the suite, not an assurance.
Esterification is the one still open, and no catalyst will fix it. Ethyl acetate and water score exactly zero against ethanol and acetic acid — the same bonds on both sides, to the decimal. A catalyst lowers a barrier; it cannot make a thermoneutral reaction downhill, and pretending otherwise would be the easiest lie on this page. Real esterification is driven by taking the water away, which is a different thing from catalysis and something this engine does not model. So it stays a miss, and we would rather say precisely why than round it up.
| Reaction class | Cases | Correct | Rate |
|---|---|---|---|
| Formation | 8 | 8 | 100% |
| Metathesis | 13 | 13 | 100% |
| Double-displacement | 8 | 8 | 100% |
| Organic | 13 | 13 | 100% |
| Negative controls | 7 | 7 | 100% |
| Overall | 49 | 49 | 100% |
A benchmark says which product. It never says whether the energy is right.
The benchmark above scores the answer: did the engine name the products a chemist would? It is silent on the number underneath — the ΔH the engine computed to get there. A model can pick every product correctly for arithmetic that is quietly 30% off, and no amount of benchmark passing would reveal it. So in August 2026 we went and checked, reaction by reaction, against published enthalpies.
The additive bond model turns out to be very good, and wrong in exactly two places — which is a far more useful result than “mostly fine.”
| Reaction | Aufbau | Measured | Error |
|---|---|---|---|
| Ammonia synthesis | −93 | −92 | +1 |
| Hydrogen combustion | −482 | −484 | −2 |
| Ethanol dehydration | +41 | +45 | −4 |
| Steam reforming of methane | +198 | +206 | −8 |
| Ethane cracking | +123 | +137 | −14 |
| Methane combustion | −694 | −802 | +108 |
| Acetic acid → ketene | +41 | +147 | −106 |
Gas-phase reaction enthalpies, kJ/mol. Computed by the shipping engine; measured values from standard thermochemical tables.
Both large errors are the same error. Carbon dioxide's O=C=O is delocalized over both oxygens, so each of its C=O bonds is worth about 799 kJ/mol — but the engine carries one generic C=O at 745, the right value for an ordinary ketone. Twice the 54 kJ/mol difference is the 108 the combustion is short by. The carboxyl group of acetic acid is stabilized the same way, which is why tearing it apart looks too easy.
We built the correction. It put methane combustion on −802.0 exactly, and carbon-monoxide combustion — a reaction that had no part in deriving it — landed within 12. Then we took it out again. Making CO₂ more stable makes every reaction that consumes CO₂ harder, and the products never got their matching credit: urea synthesis, which is exothermic in reality, flipped to endothermic and became unreachable at every temperature and pressure. The carbonyl terms are calibrated against one another, so moving one alone is not an improvement — it is a trade. Fixing it properly means re-fitting the whole set against carbon dioxide, carboxyl, ester, amide and urea together, and that is a piece of work, not a patch.
Temperature only does something if the engine knows each molecule's entropy, and ours knew 25 of them. Every reaction touching anything else silently ignored the temperature dial — which for most organic chemistry meant the dial did nothing at all. The obvious fix was to type in more values from a table. We did not want a table.
Instead the engine now computes standard entropy from three standard results, using only things it already derives: the molecule's mass, the moments of inertia of its own computed geometry, and its own vibrational frequencies. Checked against the measured values it was meant to replace, the mean error is 2.0 J/mol·K — and for a rigid molecule it is essentially exact.
The limit is just as specific. Every freely turning bond costs about 10 J/mol·K of accuracy, because a hindered internal rotation carries more entropy than the stiff vibration this treats it as. Water, carbon dioxide, methane, benzene — no rotors, no error. Butane, with three, runs short. The estimate is always low, never high, and the tests say so.
What it bought is the kind of thing that cannot be faked: ammonium chloride now has a temperature. It forms in the cold, the way it does when you hold ammonia and hydrochloric acid near each other, and it comes apart when heated, the way it really does. Before, it formed at every temperature you asked for, because the engine could not price both sides of the reaction.
The nuclear model is a liquid drop with measured values pinned over it. We measured where the smooth part is trustworthy: for heavy nuclei it is excellent — lead to within 0.05%, uranium to 0.36%. For light and mid-mass nuclei it over-binds, and the consequence is blunt: its binding curve peaks at argon, not iron. The iron peak is the single most famous fact in nuclear binding, and this model does not reproduce it.
That does not reach you, and we checked rather than assumed. Every place the app uses binding energy is either in the heavy region, where the model is accurate, or explicitly gated to it — the α-decay filter computes only from bismuth upward and consults measured values below. We verified the gate across every element from 1 to 100: everything that should decay does, nothing that shouldn't is claimed. The limitation is real, bounded, and walled off.
The engine gave the same answer every time. It was still the wrong kind of answer.
Everything on this page rests on determinism: identical inputs, identical outputs, on any machine, forever. That property held. What we had not checked is subtler, and in August 2026 it turned out to be false — a result can be perfectly reproducible and still not be a result.
Molecular geometry here is found by relaxation: nudge the atoms downhill, repeatedly, until they stop moving. The step size decays as the run proceeds, so the structure settles. Except ours had a floor. Below a certain size the steps stopped shrinking, and after roughly 458 iterations the molecule was no longer settling — it was walking, at a fixed stride, indefinitely. Deterministically. The same walk, the same stopping point, every single run.
So the geometry the engine reported was not the shape the molecule wanted. It was wherever the walk happened to be standing when the loop ran out. 18-crown-6’s size wandered between 3.03 and 3.30 Å depending only on how long we let it run — up, then down, then up, with no sign of converging on anything.
The fix was one line: let the schedule cool all the way. The same molecule now reads 3.0916 Å at 1,200 iterations, and 3.0916 Å at 24,000. Across a corpus of 32 molecules, from water to 21-crown-7, every one settles.
Converged, this engine prefers anti, and disagrees with the measurement. That is not a new disagreement — it is the same one, arrived at twice. Our from-scratch Hartree–Fock work had already concluded the engine prefers anti for hydrazine through five successive basis rungs and a relaxed torsion scan, and that closing the gap needs correlation the method does not have. The geometry layer looked like it disagreed with that. It did not. It had simply never converged.
Two independent layers now agree with each other and both disagree with the experiment. That is a worse-looking result than the one we had yesterday, and a far more honest one: we can no longer count hydrazine as something the engine gets right.
We ran the engine on a second processor. It returned the same chemistry and different numbers.
The section above is about a result being reproducible without being settled. This one is about a result being reproducible without being portable — and it was found the only way it can be, by buying a second machine with a different instruction set and running all 481 tests on it.
Same source, same compiler build, Apple silicon on one side and Intel on the other. Water came out at 103.5257° on both machines. Its raw coordinates differed by 49%.
Both of those are true at once, and the reason is worth stating plainly, because it decides what the word deterministic can honestly be made to carry. A molecule’s orientation in space costs no energy — rotate the whole thing and nothing resists. Every other coordinate has a restoring force that pulls a rounding error back; that one does not, so a difference in the last bit of a sine moves it freely and permanently. The molecule was identical. Its address was not.
So the claim this engine can defend is determinism of the algorithm: the same input gives the same chemistry, with no sampling and no temperature, on any machine. It is not bit-identity of coordinates, and it never was — we simply had no way to see the difference while everything ran on one architecture. We would rather define that ourselves than have a reviewer find it, and it is the formulation that survives the next implementation, because purpose-built hardware would be a third kind of arithmetic and would not reproduce either machine’s bits.
The interesting one was benzene. Its ring came out bent — 0.049 Å out of plane on one machine, 0.107 Å on the other, where a real benzene is flat to under 0.001 Å. Nothing in the model was holding it down: the term that keeps a double bond planar had been switched off for rings, so an aromatic ring’s flatness was whatever else happened to leave behind.
A bent ring is not a cosmetic problem. Benzene’s symmetry makes two of its frontier orbitals exactly equal in energy, and bending it splits them — by 0.0067 eV on one machine and 0.0306 eV on the other, where the true answer is zero. The gap the app draws inherited the error: 2.7525 and 2.6661 eV against 2.7758 for a ring that is actually a hexagon. The fix was to let aromatic rings feel the term that was already there, for the reason benzene is flat in the first place — its own π system. Saturated rings still pucker, as they must.
Four years of testing on one kind of processor never surfaced any of this, and not because the testing was careless. A single architecture cannot tell you which of its answers are yours and which are its. The second machine cost less than a laptop and found three real defects on its first afternoon.
The engine gave two different molecules the same answer — to the last bit.
cis- and trans-2-butene are different substances. They boil at different temperatures, they store different amounts of energy, and a chemist can separate them. Asked for the entropy of each, the engine returned 272.30527588930033 J/mol·K for one and 272.30527588930033 for the other — identical to the final digit.
That is not two answers that agree. It is one answer, given twice, by a program that could not see a difference. The two molecules have the same atoms joined by the same bonds; they differ only in which side of the double bond each methyl group sits on. The geometry was being built from the bond list alone, so the distinction never entered the arithmetic.
The fix does not add a rule about cis and trans. It derives the constraint: the molecule’s own stereochemical descriptor already says which configuration it is, and ranking the two substituents on each carbon is a question the bond graph can answer on its own. The geometry is then built to respect it.
Both methyls on the same side. They crowd each other — and that strain is what the engine kept getting wrong.
Methyls on opposite sides. Nothing comes close enough to push, which is why this one was always right.
Rendered from the engine's own output: these are the relaxed coordinates
stereoPositions returns for each isomer, not a drawing. Every figure below each model is measured
from those same coordinates in the browser.
A double bond has no torsional freedom. Twisting it breaks the overlap that makes it a double bond, so planarity is not a preference to be weighed against crowding — it wins. The engine already knew this: the main geometry routine gained a π-planarity term during the benzene work, derived rather than fitted (overlap goes as cos φ, so the restoring force goes as −sin 2φ, zero at 0° and 180° and zero at 90° as an unstable maximum). The stereochemical routine is a separate piece of code and had never been given it.
It needed one more thing to work. A restraint stiff enough to flatten a crowded double bond is also stiff enough to pull the molecule apart, and our first attempt did exactly that. The main routine avoids it by treating bonds as constraints rather than springs — every bond is pushed back to its proper length after each step, so no angular force can stretch one however strong it is. With both in place, both isomers come out flat, with identical bond lengths, on both processors. A pair of mirror images now measures as an exact pair: equal and opposite, to four decimal places.
Which left one honest question: where had the missing 90% gone? Entropy has a rotational part, which depends on a molecule’s shape, and a vibrational part, which depends on how softly it flexes. The shape was now right. The vibrations were being computed from a geometry rebuilt out of the bond list — and cis and trans have the same bond list, so both isomers were being handed the same spectrum, and the entire difference had to come out of the rotational term alone.
The engine already had the physics. Its torsion model gives a double bond a barrier of about 65 kcal/mol with two-fold periodicity, so both flat forms are stable and whichever one it starts in is the one it keeps. It had simply never been started in the right place. Handing the vibrational calculation the stereochemically correct geometry costs nothing but the starting coordinates.
The physics is legible in the modes themselves. cis-2-butene’s three softest vibrations come out at 450, 567 and 710 cm⁻¹ against trans’s 653, 714 and 771. The crowded isomer is genuinely floppier, and a floppier molecule holds more entropy — which is the whole of why these two substances differ, and it was missing from both totals until the calculation was allowed to see which isomer it had.
Both absolute values remain about 27 J/mol·K below the measured ones, for the reason they always were: a vibration the engine cannot derive contributes nothing rather than an invented frequency. That shortfall is nearly identical for two molecules sharing a constitution, so it cancels in the difference — which is why the difference is the quantity we publish and the absolutes are the quantity we flag.
Four numbers came out of this molecule: +4.94, +0.55, +0.42, +4.51. Three of them were wrong, and the first was wrong while looking the most convincing. What separated the last one was not a better fit but a structure we could defend and a term we had stopped leaving out — which is the argument for checking shapes rather than totals, made at our own expense.
And then we could not show it. The engine had told the two isomers apart since 1.17.0 and had held the double bond flat since 1.18.0, but the code that turns a molecule into a picture asked for its coordinates by a route that quietly discards stereochemistry — so a correct engine produced two identical drawings. The last thing to learn the difference was the one place a person actually looks. It is fixed in 1.19.0: Tools → Stereochemistry turns both isomers side by side on the engine’s own coordinates, with the entropy derived for each and the gap against Kilpatrick underneath — including the note that the absolutes are still 27 J/mol·K short.
There is a second confession in that fix. The first attempt bolted a stereochemistry-aware branch onto the general layout function — when a stereo-carrying path already existed a few feet away, did more (chiral centres as well as double bonds), and separated the two isomers more cleanly than the new code managed. A capability was rebuilt, worse, beside the original. The tests now pin both halves of the split, because one asserting merely that stereochemistry works somewhere would not have caught it.
Two misses. Two different fixes.
The benchmark's two organic misses were both eliminations — a stable molecule shedding a small one: ethanol → ethylene + water (dehydration), and ethanol → acetaldehyde + hydrogen (dehydrogenation). Both are uphill in bond energy, and the engine's rule was a bond-energy rule, so it abstained. They looked like one problem — a missing entropy term (−TΔS), the driving force of a small gas molecule escaping at temperature. They turned out to be two.
Aufbau now judges reactions by free energy, ΔG = ΔH − T·ΔS, not bond enthalpy alone. Above a crossover temperature the entropy of the escaping water outweighs the uphill bonds, and the engine derives ethanol → ethylene + water on its own — no template, no lookup. The same term makes ammonia synthesis reverse when heated — the real Haber trade-off, which no bond-energy rule can produce — and it leaves every negative control inert at every temperature. Dehydration is now correct; the benchmark moved to 48 of 49 at the time.
The second miss was a different kind of problem, and a more interesting one. Dehydrogenation starts from the same reactant as dehydration — ethanol — but wants a different product, acetaldehyde. A deterministic engine gives one answer per input, and dehydration is the more favorable one; acetaldehyde is the catalytic product a copper surface selects by lowering one path's barrier — kinetic control, not thermodynamics. So it needs a catalyst in the input — and the honest thing was to derive what the catalyst does, not look it up. It turns out you can: a metal's catalytic character is written in its electron configuration. Copper's filled d¹⁰ shell binds weakly enough to abstract hydrogen without cracking carbon–carbon bonds — so over copper, ethanol gives acetaldehyde, and the engine now derives exactly that. With the catalyst supplied, the benchmark reached 49 of 49 — the two identical-reactant rows resolve because they are no longer the same input.
Those two figures are where this stood when the fixes landed. The benchmark reads 49 of 49 today. It got there by giving esterification the driver it actually needs — taking the water off as it forms — rather than by loosening anything: the reaction is thermoneutral to the decimal, so no threshold could ever have admitted it. It went down before it went up: the scoring got stricter three times — a declined reaction was being counted as a pass, and two rows were being scored on a product formula that cannot tell isomers apart — taking 49 to 46. All three have since been won back properly — one by giving the engine a mechanism instead of a better number, one by letting a base license a bond the engine had been forbidden to make, and the last by supplying a driver rather than relaxing a threshold. The stricter scorer was never reversed; the engine climbed back through it. The story above is how the two eliminations were fixed; the story at the top of this page is what the stricter scorer found, and what closing its findings actually took.
Catalysis, written in the periodic table.
Ask a chemist why copper turns ethanol into acetaldehyde but an acid turns it into ethylene, and the honest answer is a table of facts: this metal for that reaction. We wanted the other kind of answer — the one where the behaviour follows from something. It does. A transition metal's catalytic character is encoded in its outer electrons, and Aufbau already computes those for every element. So the catalyst isn't a lookup; it's derived.
Copper is [Ar] 3d¹⁰ 4s¹ — a filled d-shell. That single fact is the whole story. A full d-band sits low and binds adsorbates weakly, so copper grips a molecule just hard enough to pull a hydrogen off (dehydrogenation) but too weakly to tear a carbon–carbon bond apart (cracking). Run the chain — d-band filling → band centre ε_d = W(½−f) → binding strength → the barrier to break each bond — and a single number falls out: how much cracking is harder than hydrogen abstraction. It is largest for the filled-d¹⁰ coinage metals. Copper is the gentlest catalyst on the row, and the math says so, from its configuration alone.
| Metal | d-config | Derived archetype | What it really does |
|---|---|---|---|
| Ti / V | d²–d³ | oxophilic | Ziegler–Natta, oxidation |
| Fe / Co / Ru | d⁶–d⁷ | dissociative | ammonia synthesis, Fischer–Tropsch |
| Ni / Pd / Pt | d⁸ | hydrogenation | hydrogenation, reforming |
| Cu / Ag / Au | d¹⁰s¹ | gentle | selective dehydrogenation, epoxidation |
| Zn | d¹⁰s² | Lewis acid | a promoter — not a surface catalyst |
Most of the real periodic table of catalysis falls out of the outer electrons alone —
iron's half-open d-shell dissociates nitrogen (the Haber process); copper's closed d¹⁰ selects gently;
zinc's closed shell with a filled s does neither. Reproducible from the shipping build:
aufbau-engine --catalyst <Z>.
selects a product
Over copper, ethanol has two downhill exits — ethylene (favoured) and acetaldehyde. Copper lowers the barrier of the dehydrogenation path, so acetaldehyde forms faster even though ethylene is more stable: kinetic control. The engine now returns acetaldehyde over Cu, ethylene over none.
enables a reaction
Nitrogen and hydrogen in a bottle just sit there — the N≡N triple bond is a wall. Iron's open d-shell dissociates it, and only then does ammonia form. Aufbau now leaves N₂+H₂ inert without a catalyst and makes ammonia with iron — honest about a reaction that genuinely needs one.
Two engines, asked where matter ends.
The same honesty that runs through the reaction benchmark applies far outside chemistry. Aufbau carries two independent engines that never share a table: an electron engine (the Madelung n+ℓ rule that builds any element's electron configuration) and a nuclear engine (the measured binding energies of the 2020 Atomic Mass Evaluation wherever a nucleus has been measured, and a semi-empirical mass formula beyond the measured chart). We asked both the same question — where does matter end? — and they disagree. The disagreement is the result: each engine's answer maps precisely onto the physics the other one can see and it cannot.
“There is no edge.”
Swept out to Z = 20,000 the filling rule never falters — it reproduces the predicted 8th period exactly (the 5g block opens at element 121), then keeps opening orbitals endlessly. The rule has no natural terminus. Reality ends the table by physics this engine can't see — relativity (near Z ≈ 137 the 1s electron nears light-speed) and vacuum breakdown (near Z ≈ 173). Its endlessness is a clean map of exactly where relativity takes over.
“The edge is much earlier.”
The nuclear engine draws the real shape of matter. Its formula alone gives the binding-energy curve's broad mid-mass maximum — why fusion stops and fission begins — though it puts that maximum near A ≈ 48 rather than at iron, the kind of miss a smooth formula makes; with measured binding energies the engine has it where it is, at nickel and iron. Energy also shows something easy to get wrong: α-decay is energetically open well below bismuth — platinum, mercury, even lead-208, which has never been seen to decay. Whether a nucleus counts as stable is a question of how fast, set by forces this engine does not contain. The true edge of matter is nuclear, near Z ≈ 120–126 — well below where the electron rule even gets interesting.
- Z
- proton number — how many protons a nucleus has. It alone decides which element you have: Z = 82 is lead, Z = 114 is flerovium.
- N
- neutron number — how many neutrons share the nucleus with those protons.
- A
- mass number — the total count of protons and neutrons together, A = Z + N. “Flerovium-298” means A = 298 (Z 114 + N 184).
- α-decay
- alpha decay — a nucleus shedding a tight helium-4 cluster (2 protons + 2 neutrons). The energy this releases is the α-decay Q plotted below; lower Q means the nucleus is more stable against it.
- magic numbers
- special values of Z or N — 2, 8, 20, 28, 50, 82, 126 … — where a nuclear shell is exactly filled, giving extra stability. They are the nucleus's echo of the noble-gas electron shells.
Sweep the engine across the superheavy region and read off the energy that drives α-decay — lower means more stable. Where nuclei have been measured or evaluated the engine uses those binding energies; beyond them, only the formula speaks. Two features appear: a low point at flerovium, Z = 114, in the evaluated region, and the model's own dip near Z ≈ 122–124 beyond it, before the steep climb toward the fission cliff.
Nuclear theory predicts an island of stability: superheavy nuclei made unusually long-lived by shell closures, centered near Z = 114, N = 184 (mass 298 — the doubly-magic “flerovium-298”). The shipped engine applies one list of magic numbers to both protons and neutrons — 2, 8, 20, 28, 50, 82, 126 — so above N = 126 it has no neutron shell closure at all. The model's dip near Z 122–124 in the chart above is really the lone proton closure near 126 acting by itself — a shadow, not the real, neutron-anchored island. That yields a sharp, falsifiable prediction: because the model lacks the N = 184 closure it cannot place the island correctly — but supply the shell model's predicted closures (proton 114, neutron 184) and the island should snap to the textbook spot. We ran exactly that, mapping α-decay energy across the nuclear plane before and after, with the shipped engine left untouched:
| Measure | Shipped engine (one list) | + shell-model closures (Z 114, N 184) | Textbook |
|---|---|---|---|
| Island location | none — valley drifts to the neutron-rich edge | Z ≈ 111–114, N = 182, A ≈ 296 | Z 114, N 184, A 298 (Fl) |
| Z = 114 α-decay energy | +6.76 MeV | +3.91 MeV | — |
| Valley trace (best N) | runs off the scan edge | locked at N = 182 | N ≈ 184 |
Reproducible from the shipping build: aufbau-engine --config <Z>
(electron sweep), aufbau-engine --binding <Z> (most-bound isotope, binding per
nucleon, α-decay energy), and aufbau-engine --island — the experiment below is a
first-class command that drives the same engine with the proton and neutron
shell-closure lists separated, printing the before/after directly.
A textbook ordering, from overlaps the engine was never shown.
Put six ligands around a transition metal and its five d orbitals stop being equal: two point straight at the ligands and are pushed up, three point between them and are not. The gap is Δo, and ranking ligands by it gives the spectrochemical series — one of the oldest empirical orderings in inorganic chemistry, and for a century a thing you looked up rather than derived.
Aufbau computes it. Six ligands are placed octahedrally at the sum of their covalent radii, the complex is solved, and the ligands are ranked by the splitting that comes out. Nothing in that path is fitted to the answer: the orbital exponents and energies are a published Extended Hückel table, the bond lengths are radii sums from a crystallographic survey, and the series itself is never given to the engine. It is used afterwards, as a check.
For scandium, the computed ranking from weak field to strong, against the measured one:
measured I < Br < S < Cl < F < O < N < P < C
The whole weak-field end is right — I < Br < S < Cl — and so is the strong-field end. Six of the nine sit in the correct order relative to one another, out of nothing but computed overlaps.
The ordering, and π back-bonding with it.
Carbon monoxide is the classic π acceptor: the metal gives electron density back to an empty orbital on the ligand. Nothing was added to the model for this. CO's accepting orbital is simply one of CO's own molecular orbitals, so it appears the moment a real CO is put in and the overlaps are computed. A bare atom reports exactly zero — it has no such orbital, and the engine says so rather than rounding. Back-bonding also switches off at the start of the row, where scandium is d¹ and has no electrons to give away, which is why scandium carbonyls are not a thing.
It gets worse across the row.
Scandium scores six; copper scores three. The mechanism is visible — scandium's d level sits above every ligand level, which is the clean donation regime, while copper's sits below most of them and the interaction inverts — but the real spectrochemical series is very nearly the same for every metal. A model whose ordering degrades across one row is wrong in a way we can name and have not yet fixed. Five of the nine donors are also bare atoms standing in for ions: F rather than F⁻. We spent some time believing that stand-in was the largest remaining approximation, and we do not currently know whether it is. See below for two attempts to find out, both of which failed in the experiment rather than in the chemistry.
- Δo
- the octahedral splitting — the energy gap between the two sets of d orbitals in a six-coordinate complex. It sets a transition-metal compound's colour, its magnetism, and much of its reactivity.
- t2g, eg
- the two sets. t2g is the three orbitals pointing between the ligands; eg is the two pointing straight at them, which is why they are pushed higher.
- spectrochemical series
- ligands ordered by the splitting they produce, from weak field (iodide, bromide) to strong field (phosphines, carbon monoxide). Determined experimentally from absorption spectra, and famously almost independent of which metal you use.
- π back-bonding
- the metal donating electron density back into an empty orbital on the ligand — the reverse of ordinary bonding, and the reason CO and cyanide sit at the strong-field end.
- Extended Hückel
- a first-principles molecular-orbital method that builds orbitals from atomic ones and their overlaps. Deliberately simple: no fitting to spectra, no trained weights, and every number in it can be traced.
Six explanations, and the last one explains the rest.
The ligand-field result above gets six of nine right and degrades across the row. Over three days we had six explanations for that. Five were wrong — two of them wrong in ways we published first and withdrew later. The sixth turned out to explain not only the failure but the part that already worked, which is the thing that makes it believable.
One: we were reading the answer out badly. There is more than one defensible way to extract the splitting from a computed complex, so we built four. They disagree with each other about as much as they disagree with experiment. Closed.
Two: the atoms should know their own charge. The standard fix for that had been written into the code as the recommended next step and never once run. Pointed at the series it produced almost no answer at all — most complexes never converged. Chasing that found a real defect in how the calculation fills orbitals, which was worth keeping. With every ligand finally resolving, the ordering got worse. Closed.
Three: the ligand energies are wrong. We swept them and found nothing, and said so here. That was wrong twice over: the sweep moved every ligand by the same amount and so could not see a defect that moves them apart, and the follow-up measured a number the program keeps in a table it never reads. Both claims were withdrawn. The energies are fine.
Four: the method lacks the physics. Much of what separates a strong-field ligand from a weak one is electron density flowing back from the metal, and this engine's is about twelve times too weak. Unlike the others, this one could be proved wrong: if it were the only defect, the ligands that cannot accept any density back would already be in the right order. Seven of the nine accept exactly none — and scored against each other alone, copper gets two of seven. Closed.
Five: the molecules are being penalised for their substituents. Hydrogen peroxide and ammonia carry extra atoms the bare halides do not, and adding one hydrogen to fluorine appeared to cost nearly half its splitting. It did not. We had placed that hydrogen at ninety degrees to the metal — sticking out sideways, where it does not belong — while every real ligand in the program points its substituents away. Rebuilt correctly the cost is six per cent. Withdrawn.
Six: the rule that decides how strongly a metal and a ligand interact is the wrong rule. That interaction strength is not measured; it is estimated by a formula from 1952 which multiplies the overlap between two orbitals by their average energy. We recovered the number the program actually uses and compared it against that formula across all seven donors. It matches to within four per cent, with a constant of 1.75 — which is the value the formula's authors published.
Averaging two energies means a ligand that holds its electrons very tightly is scored as interacting strongly. Chemically that is upside down: an atom with a deep, tightly-bound pair is a reluctant donor. The formula rewards exactly the wrong thing — and the ligand energies span seventeen electron-volts across this series while the overlaps barely move, so that one term decides the whole ordering.
It explains the part that worked.
Among the halides alone the computed order is exactly right for every early metal — iodide, bromide, sulfur, chloride, fluoride, in that order, with no exceptions. That had looked like partial success. It is the same rule succeeding for a coincidence: across the halides, holding electrons tightly and being a strong-field ligand happen to run together, so rewarding the wrong thing gives the right answer. Step outside that group, to water and ammonia, and the coincidence ends. An explanation that accounts for a success as well as a failure is worth more than one that only accounts for the failure.
We did not try a seventh parameter.
Every one of the first five was a number: an energy, an exponent, a distance, a charge, a choice of which root to read. All of them move ligands around within the same rule, which is why all of them failed, and why a sixth would have too. What is wrong is the rule. Replacing it is a different method rather than a different setting — a much larger commitment, touching every result this engine computes that way, and not something to drift into because it is the next thing on a list.
- spectrochemical series
- the ranking of ligands by how strongly they split a metal's d orbitals. Nearly the same for every metal, which is the property this model does not reproduce.
- overlap
- how much two orbitals occupy the same space. Large overlap is a necessary condition for a strong interaction, and across this series it barely varies — which is how the energy term came to decide everything.
- approximation
- a stand-in for a quantity too expensive to compute properly. Useful, and different from a parameter: a parameter is a number you can change, an approximation is a decision about what to calculate.
- elimination
- closing a hypothesis by measurement. It costs the same as confirming one and is worth the same, provided somebody writes it down — including the ones that were your own mistake.
We bent the rule instead of replacing it. The one gain was a coincidence.
The note above ends on a decision not to act: the rule that decides how strongly a metal and a ligand interact rewards the wrong thing, replacing it is a different method rather than a different setting, and that is too large a commitment to drift into. That conclusion was reached by argument. Before spending weeks on it, we wanted it tested.
There is a way to test it cheaply. The 1952 formula has a published refinement: the same product of overlap and average energy, but with the constant increased when the two energies are badly mismatched. That is not a parameter we invented to fit this problem — it is the rule's own authors, twenty-six years later, addressing the objection we had just rediscovered. If a weighted version of the rule can order the series, the rule is repairable. If it cannot, the argument for replacing it stops being an argument.
We added the weighting as an opt-in strength, dialled from strongly negative to strongly positive, with the zero setting asserted to reproduce the plain constant bit for bit. So the experiment can be run on the shipping physics without shipping any of it. Three things came out, and the first two are clean negatives.
Damping instead of strengthening is worse everywhere. That was the intuitive repair — the formula over-rewards tightly-held electrons, so weaken the coupling where the mismatch is largest — and every metal gets worse — scandium loses two thirds of its score.
The published weighting does nothing at all. Translated into our dial it sits near the low end, and there the series is unchanged for every metal we tested. Any movement at all requires two to six times the literature value — at which point it is no longer the published refinement, just a knob.
And the two actual errors survive every setting. Fluorine comes out the strongest-field ligand of all nine on chromium, when it belongs in the middle of the series — below oxygen, nitrogen and phosphorus. Ammonia comes out the weakest of all nine on copper, when it belongs near the top. Both are still exactly there at every value of the dial, in both directions. Those are the failures that matter, and the weighting never touches them.
Which left one exception. Iron. Iron's weak-field end is inverted at the default setting — sulfur ranked below bromine and iodine, when it should be above both — and at the high end of the dial it comes out right, with carbon monoxide strongest. That was the only structural improvement anywhere in the sweep, and it is the kind of result that is easy to write up as progress.
It is not progress. The first clue is that iron does not approach the right answer, it wanders onto it:
low S < I < Br still wrong, differently
high I < Br < S correct
A correction that addressed the cause would not pass through a second wrong ordering on its way to the right one. What is actually happening is arithmetic. Sulfur sits too low for every late metal — that is the error — and the weighting pushes sulfur up harder than iodine, because sulfur's shallower energy gives it the larger mismatch. But that extra push is very nearly the same size for all four late metals, while the gap it has to cross grows steadily across them:
| Metal | Inversion to cross | Extra push it gets | Crosses? | Ordering correct? |
|---|---|---|---|---|
| Iron | 0.16 | 0.49 | yes | yes |
| Cobalt | 0.34 | 0.49 | yes | no |
| Nickel | 0.59 | 0.45 | no | no |
| Copper | 0.72 | 0.34 | no | no |
Electron-volts. The inversion is how far sulfur sits below iodine at the default setting; the push is how much more the strongest weighting adds to sulfur than to iodine. A fixed push against a growing gap is a threshold, not a correction.
So iron is simply the late metal whose error is narrowest — narrow enough for a roughly constant nudge to step over it. And cobalt shows the nudge is not even sufficient when it does clear the gap: cobalt's sulfur passes iodine and the ordering is still wrong, because sulfur has to pass bromine too. Iron is the one metal where both crossings happen to land.
A decisive negative, for an afternoon.
No new chemistry — but the argument for replacing the rule is no longer only an argument. Every route through the rule's own settings is now closed by measurement rather than by reasoning, including the setting its authors added for exactly this objection. That matters because the replacement is expensive: this coupling is shared by every result the engine computes this way, including band structures and coordination preferences that currently work. Spending weeks on a rewrite is a defensible decision. Spending them without first running the cheap experiment would not have been.
We did not keep the best number.
There is a setting where chromium scores seven of nine — the single best cell anywhere in the sweep, better than anything else on this page. We left it on the floor and shipped the dial at zero. Tuning it would have meant fitting a physical constant to a nine-point integer score, on one metal, at a value the literature does not support; and the orderings show plainly that the two real errors are still there underneath that seven. This page has already published one result that was produced exactly that way, and withdrawn it. A number that improves while the failure it is supposed to explain stays put is not a result.
- off-diagonal
- the number standing for how strongly one orbital interacts with another — as opposed to the diagonal, which is what each orbital costs on its own. In this method it is estimated by formula rather than computed, which is what makes it the approximation under test.
- Wolfsberg–Helmholz
- that formula, from 1952: overlap multiplied by the two orbitals' average energy, times a constant near 1.75. Its weighted form, from 1978, raises the constant when the two energies are far apart.
- threshold
- a change that flips an outcome by crossing a boundary rather than by addressing a cause. It looks identical to a fix on any single case, and is told apart by asking whether the size of the change tracks the size of the error. Here it does not.
- opt-in
- an experimental setting that defaults to off and is asserted to leave the shipping result bit-for-bit unchanged when it is. It lets a falsifying experiment be run against real physics without altering the physics anybody uses.
- near-degeneracy
- two outcomes close enough in energy that their order is decided by whatever is least accurate in the calculation. A real phenomenon, and a tempting explanation for any ordering error — which is why it needs checking against the cases it predicts should be fine.
Four repairs for one defect. All four made it worse.
The two notes above leave one thing unexplained. The computed ordering is decent for the early metals and falls apart by the end of the row — yet the real spectrochemical series is famously almost the same whichever metal you use. A model that gets worse across a row is wrong in a way that has a name, and it had one obvious suspect.
The metal's own energy level is the only quantity in the calculation that moves much. It drops by about five and a half electron-volts from scandium to copper, while every overlap in the problem varies by a tenth. If something is producing a metal-dependent answer, that is where it would come from.
And there is real chemistry pointing the same way. The series is measured on ions — chromium(III), iron(II), copper(II) — while the engine uses values for neutral atoms. Stripping electrons off a metal does two things to its d shell: it pulls the level down, and it pulls the orbital in. Both are testable without committing to any particular model of a cation: apply each one as a scan and ask whether any setting works, before building a parameterisation that assumes one does.
| What we tried | Why it should have worked | What happened |
|---|---|---|
| Lower the metal's level | real complexes are cations | worse at every depth |
| Contract the metal's orbital | ionisation pulls the d shell in | worse — and the metals diverge |
| A different coupling rule | the metal's level cancels out of it | worse, by a full point |
| That rule, on one term only | to rule out a side effect | identical — there was no side effect |
Each row is a scan, not a parameterisation: a dial that reproduces the shipping engine exactly at its default setting, so a falsifying experiment can be run against real physics without altering the physics anybody uses.
| Ranked by | Sc | Ti | V | Cr | Mn | Fe | Co | Ni | Cu |
|---|---|---|---|---|---|---|---|---|---|
| Overlap alone | 5 | 4 | 5 | 6 | 6 | 6 | 6 | 6 | 6 |
| The full calculation | 5 | 5 | 5 | 5 | 5 | 3 | 3 | 3 | 2 |
Out of seven, against the measured series, on the five donors that are bare atoms plus bare oxygen and nitrogen — all with the same number of orbitals, so none is flattered by being a larger molecule. The two rows cross at chromium and move apart afterwards.
The contraction result is the one that matters, because contraction is the direction ionisation actually goes. It does not merely fail to help. At the tightest setting the nine metals produce nine different orderings — every metal with a series of its own, which is the exact opposite of the metal-independence the whole idea was introduced to explain. The scan could have shown otherwise: contraction changes each donor's overlap by a different amount, by about eighteen per cent across the set, so a repair was expressible and simply did not appear.
One. We expected that pushing the metal far enough down would make the interaction weak, and that in that limit the ordering would be decided by the overlaps — which, as the numbers above show, are the part that works. It does not happen. Once the metal drops below the ligands the splitting inverts: the orbitals that should be pushed up are pushed down hardest, and the answer comes out negative rather than small. The model does not degrade gracefully into its own limiting case, which is a fact about the method worth knowing on its own.
Two. The alternative coupling rule multiplies the two energies together and takes a square root, instead of averaging them. That form factorises — the metal's level becomes a common factor and should cancel out of any comparison between ligands, which is precisely the metal-independence we were missing. It does the opposite: seven distinct orderings where the old rule gives six. So the two defects on this page are not one defect. That is the most useful thing here, and we believed the reverse until it was measured.
The case for a rewrite, built from negatives.
One contrast survives all of it. Ranking the ligands by overlap alone — no energies at all — does not get worse across the row. It gets better. Ranking them by the full computed splitting gets worse, over exactly the same metals. Whatever makes the answer depend on the metal enters through the energy side — and every cheap route into the energy side is now closed by measurement rather than by argument. The note above deferred a method replacement on the grounds that it is expensive and touches results that currently work. That reasoning is unchanged; what has changed is that the alternatives are no longer hypothetical. They were tried.
We did not keep the setting that scored better.
Expanding the metal's orbital rather than contracting it improves nearly every metal by a point. We are not using it. Ionisation contracts — an expanded orbital is the physics running backwards, and the improvement is a uniform lift that leaves the metals as disagreed as before, so it fixes the score without touching the thing the score is supposed to measure. It would look like the best result on this page and mean nothing. That is the same trade refused two notes ago, and it does not get easier by being offered twice.
- scan
- a dial swept across a range to ask whether any setting produces the wanted behaviour. It answers that question before anyone builds a model that assumes the answer is yes — and a null result from a scan is worth having, provided you first check the scan was capable of showing something.
- metal-independence
- the observed fact that the spectrochemical series is nearly the same for every transition metal. It is the property this model does not have, and the reason a metal-dependent error is a structural fault rather than an inaccuracy.
- contraction
- an orbital pulling closer to its nucleus. Removing electrons contracts the rest, because there is less mutual repulsion pushing them out — so a cation's d shell is both deeper and smaller than a neutral atom's.
- limiting case
- the behaviour a method falls into when one quantity is pushed to an extreme. A method that behaves sensibly in its limits is usually trustworthy between them; one that changes character, as this does, is telling you something about where it can be used.
The rare earths, separated by design — not by acid.
The rare earths run the modern world — the magnets in wind turbines, electric motors, and guided systems — and they are the hardest bulk separation in chemistry, because the fifteen lanthanides are almost chemically identical. Industry pulls them apart the brute way: roast the ore in acid, then push a nearly-inseparable mixture through hundreds to thousands of countercurrent extraction stages, leaving radioactive tailings and poisoned water behind. We wanted the other kind of answer — where the separation follows from the atom. It does. Aufbau reads which lanthanide can be pulled out cheaply, and how, from electron configuration alone.
Most lanthanides are stubbornly trivalent, but three aren't: cerium, europium, and ytterbium have a cheap one-step redox handle — a +4 or +2 ion whose electrons land on an empty, half-filled, or full 4f shell. That "magic-shell" stability is just exchange energy, which Aufbau already counts. Strip those three in one electrochemical step each, and the hard part — the stubborn trivalent remainder — is smaller before the expensive train even starts.
| Element | Ln³⁺ | Cheapest lever | Why — from the configuration |
|---|---|---|---|
| Cerium | 4f¹ | oxidise → Ce⁴⁺ | empties to the bare 4f⁰ core |
| Europium | 4f⁶ | reduce → Eu²⁺ | completes the half-filled 4f⁷ shell |
| Ytterbium | 4f¹³ | reduce → Yb²⁺ | completes the full 4f¹⁴ shell |
| Nd, Pr, Dy… | 4fn | chelate | no magic-shell redox — split by the contraction |
The computed "strong redox" set is exactly the three that industry separates this way —
from f-shell exchange counting alone, no table. Reproducible from the shipping build:
aufbau-engine --serve (the flowsheet op), or in the app under
Tools ▸ Rare-Earth Flowsheet.
Redox, one step each
Cerium is roughly half of a light-rare-earth ore by mass. Oxidise it out; reduce europium and ytterbium out — three cheap electrochemical steps, no acid roast, no ammonia. The mixture that reaches the extraction train is smaller and simpler.
The contraction as a guide
The trivalent remainder is split by the tiny lanthanide contraction — the heavier ion is smaller and more charge-dense, so a hard oxygen donor holds it a shade tighter. Aufbau ranks the donors and flags exactly where the split is tightest (for magnet metals, that's Nd/Pr) — the stages you'll need the most of.
A battery's fastest ion, found without a supercomputer.
A solid-state battery lives or dies on one number: how easily a lithium ion slips through the crystal that separates the electrodes. Measuring it takes a lab; predicting it usually takes density-functional theory on a compute cluster. Aufbau does neither — and gets the ordering right anyway.
It reads a crystal structure — the same public CIF a crystallographer downloads — and maps the energy a mobile ion would feel at every point in the cell from the bond-valence site energy: a short-range attraction to the oxygens it threads, and a screened repulsion from the framework cations it must squeeze past. The low-energy points form a network, and the migration barrier is the lowest energy at which that network first spans the crystal — the ion's easiest way through. Nothing is fitted to conductivity: the parameters are the published softBV set, and the barrier is read off the map, not trained toward it.
The screening payoff is the ranking. The cubic garnet Li₇La₃Zr₂O₁₂ — the flagship fast solid electrolyte — comes out at a lower barrier than the NASICON LiTi₂(PO₄)₃, which is the ordering every battery chemist knows. It only comes out right when the barrier is measured from the site the ion actually rests in: the garnet's deepest point is a trap the ion never sits in, and referencing to it instead would report the slow, wrong value. Getting that reference right is the difference between a screen that ranks materials and one that misleads.
The right conductor, and the right charge.
Beyond the ranking, the tool reads a structure honestly. When a crystal file labels its own oxidation states, the engine uses them: iron in LiFePO₄ enters as Fe²⁺ straight from the file rather than a guess — which matters, because the charge sets how hard that cation pushes the lithium past it. And you can watch it: the app renders the framework, the low-energy channel the ion threads, and the ion itself migrating along it — a real crystal you can rotate, zoom into, and read atom by atom.
It knows what it can't model — and says so.
This is a screen, not DFT: it overestimates absolute barriers, so the numbers rank materials rather than reproduce experiment. And it is fitted to oxide frameworks only. Hand it a sulfide or a fluoride electrolyte and it refuses — it will not score sulfur with an oxygen potential and hand back a confident wrong number. Give it a framework cation it has no parameters for and it says plainly that the barrier will read optimistically low. The refusal is the feature.
- solid electrolyte
- a solid that conducts ions but not electrons — the piece that replaces the flammable liquid in a solid-state battery. How fast it conducts is set by the migration barrier.
- migration barrier
- the activation energy for a mobile ion to move through the crystal. Lower means a faster conductor; it is the single number that most decides whether an electrolyte is any good.
- bond-valence site energy
- a deterministic, no-DFT estimate of what a mobile ion feels everywhere in a cell — attraction to the anions it bonds, repulsion from the other cations. Decades old, well-calibrated, and fast enough to sweep thousands of structures.
- NASICON, garnet
- two families of oxide ion conductor. The garnet Li₇La₃Zr₂O₁₂ is the archetypal fast solid electrolyte; NASICON LiTi₂(PO₄)₃ is a good but slower one. Ranking them correctly is the test a screen has to pass.
- softBV
- the published bond-valence parameter set the barriers are computed from. Fitted to crystal structures across the periodic table — never to ionic conductivity — so a good barrier is a prediction, not a memory.
The crystal file never said kagome.
Every other tool in Aufbau answers a question about something finite: this molecule's shape, this reaction, this metal and its ligands. A crystal is not finite. It repeats — and once it repeats, the answer stops being a list of orbital energies and becomes a band: energy as a continuous function of direction through the crystal. Same rules, same arithmetic, even the same matrix solver the molecular engine uses. The only thing that changed is the boundary condition.
The model is deliberately the plainest one that can answer the question: one orbital per site, neighbours only, and a single number t for how easily an electron hops between them. t is the unit the energies are quoted in, not a fitted quantity — which means nothing about the shape of these bands was tuned. Whatever structure appears came from the geometry.
The primitives were checked first, on purpose. A band structure is easy to produce and hard to check: almost any bug still yields smooth, plausible-looking curves. So the first thing computed was a one-dimensional chain, the least a solid can be and still have a band, whose answer is an exact cosine — E(k) = −2t·cos(ka). It matched at every sampled point. Then a square lattice, whose corners are exactly −4t, 0 and +4t. Only once those were right was anything more interesting taken seriously.
The interesting one is the kagome net — a tiling of corner-sharing triangles. Three sites per cell gives three bands, and the top one comes out perfectly flat: electrons in it carry no kinetic energy at all, anywhere in the zone. The lower two touch at a single point, a Dirac point. Neither was put in. They are what the geometry does.
A real crystal, told only which element to look at.
The test that matters is not the idealised lattice — it is a file. Handed the published CIF for the boride YRu₃B₂ and the single word ruthenium, the engine expands the symmetry, finds each ruthenium has four neighbours at 2.7413 Å, and returns the same flat band and the same Dirac point. Nobody told it about kagome. The ruthenium sits at one crystallographic position; the kagome net is simply what those positions become once the symmetry is worked out. The sister compound LuRu₃B₂ gives an identical answer from a slightly smaller cell — as it should, if the bands come from geometry rather than from which atom is at the centre.
Shapes, not energies — and no superconductivity.
Because t is a unit rather than a computed quantity, there is no eV axis here. What these results determine is the shape — which bands are degenerate, which are flat, in what order they sit — and that is precisely the part geometry alone fixes. Everything else is out of scope: nearest neighbours only, one orbital per site, no spin, no spin–orbit coupling, no magnetism. And these are single-particle bands. A flat band is the reason strongly correlated phases become possible — quench the kinetic energy and interactions win — but it is not itself superconductivity. These borides do superconduct. Aufbau does not compute that, and does not claim to.
- band structure
- for a crystal, energy is not a list of levels but a continuous curve versus direction and wavelength of the electron wave. Which bands are filled, and whether they touch or leave a gap, is what makes a material a metal, a semiconductor or an insulator.
- Γ, K, M
- named landmarks in the space of electron wavelengths — the centre, a corner and an edge-midpoint of the repeating unit. A band structure is conventionally drawn along a tour between them — the Γ → K → M → Γ labelled along the bottom of the plot the app draws.
- flat band
- a band whose energy does not change with direction. An electron in it has no kinetic energy to speak of, so even weak interactions between electrons dominate — which is why flat-band materials are hunted for magnetism and superconductivity.
- Dirac point
- a single point where two bands meet. Near it electrons behave as if they were massless; it is the feature that made graphene famous.
- kagome
- a pattern of corner-sharing triangles, named after a Japanese basket weave. Its geometry alone forces a flat band — which is why the metals built on it are studied so heavily.
- tight binding
- the simplest honest model of a solid: keep one orbital per atom and one number for how easily an electron hops to a neighbour. The same linear-combination-of-orbitals idea Aufbau already uses for molecules, solved on a lattice that repeats instead.
We checked the answer key.
To find out where an engine is wrong you need a large body of chemistry it has never seen. We use the Open Reaction Database — reactions extracted from published patents and papers, 2.4 million of them, of which 153,237 fall inside the elements Aufbau covers. It is a genuinely valuable public resource and this work depends on it.
Before trusting anything we measured against it, we checked something simpler than chemistry: can the questions be answered at all? A product cannot contain an element that appears in none of its ingredients. That is not a theory about reactivity — it is counting. So we counted, across every recorded reactant, reagent, catalyst and solvent.
These are not fake reactions. They were run, they worked, and somebody wrote them up. What is missing is in the record: a starting material never survived the trip from prose into structured data. Across those 7,608 the shortfall comes to 26,864 carbons, 15,867 nitrogens and 7,063 fluorines — and in 56% of cases it is six or more heavy atoms at once, a whole fragment rather than a stray atom. No engine can get these right. Carbon does not come from nowhere, and a model that produced the "correct" answer here would be doing something other than chemistry.
A scoring footnote would be the least of it. This corpus is not a scoreboard to us — it is the instrument we use to find missing physics. The method is straightforward: where the engine and the literature disagree, look for the mechanism we have not modelled yet, then derive it. And the most valuable disagreement of all is the near miss — the engine assembles part of the recorded product but not the whole of it. That says we are one step short, which is the most actionable thing a failure can say.
So we sorted by it. Five of every six rows in that bucket turned out to be reactions whose missing piece was never on the bench. The engine had built everything it was given; it could not have finished, because the atoms to finish with were not in the problem. Every one of those looks exactly like a gap in the chemistry, and none of them is one. Chase that signal honestly, as we had been about to, and you spend a week deriving physics to explain somebody's incomplete data entry — and if you are unlucky, you find something that "fixes" it, and ship it.
Audit the exam before you grade the student.
Incompleteness is a known property of literature-derived reaction data, not a defect peculiar to this database — reagents get named in prose and not in structures, a quantity appears without a compound, a step is "the usual workup". Text extraction cannot invent what the paper did not print. The useful move is simply to measure it, which takes an afternoon and an atom count, and then to know which part of your error bar belongs to the model and which part belongs to the exam. We now run that check first, and the filtered set is what tells us where to look next.
We did not quietly drop them from the score.
Discarding the questions you got wrong is how a benchmark stops meaning anything. So the rule is deliberately narrow: a reaction may be set aside only for a property of the data — atoms missing — that is decidable without ever running the engine, and the filter is built so that it cannot see a result even in principle. The excluded list was fixed once, in advance, and is checked into the harness. Our headline accuracy is still measured over everything, unflattering 5% included.
- Open Reaction Database
- an open, community-run collection of chemical reactions drawn from the published literature and from industrial submissions, released under a permissive licence. It is the closest thing the field has to a public test set, and nothing here is an argument against using it — only for checking it first.
- atom balance
- the bookkeeping check that every atom in the products can be traced to an atom in the inputs. Chemistry conserves atoms, so a product carrying an element that nothing supplied is a sign that the record is incomplete — not that the reaction was.
- heavy atom
- any atom that is not hydrogen. Chemists count them as a rough measure of molecular size, which is what makes "six heavy atoms missing" a meaningful unit: it is about the size of a benzene ring.
- reagent, catalyst, solvent
- the supporting cast of a reaction as recorded — the things that assist, accelerate or dissolve rather than ending up in the product. They are all counted here, which is what makes the 5% a floor rather than an estimate.
Aufbau cannot rank an acid. Here is exactly why.
Acetic acid is about a hundred billion times more acidic than ethanol. Put either one with sodium hydroxide and ask the engine what happens, and it gives both the same score: 0.0. Not close — identical, to the last digit.
The reason is arithmetic. Neutralising an acid written X–O–H breaks an O–H bond and a sodium–oxygen bond, and forms a sodium–oxygen bond and an O–H bond. Aufbau prices a bond by the two elements it joins and its order, so those four terms cancel exactly, whatever X is. Hydrochloric acid, whose H–Cl is not an O–H, comes out +124 and reacts as it should. Every acid built on an O–H scores zero.
The textbook reason a carboxylic acid is acidic is that its anion spreads the negative charge over two oxygens, and an alkoxide has nowhere to put it. We added exactly that: a stabilisation for the carboxylate, beside the other corrections the engine already makes for delocalisation. It ranked the acids correctly. It passed the 49-reaction benchmark. It passed the full engine test suite with no failures.
Then we ran it against published reactions it had never seen, and it lost: 428 answers it had been getting right, for 153 gained. Halving the correction made the loss-to-gain ratio worse, not better (2.8 became 4.3), which is the signature of a term aimed at the wrong thing rather than one that is merely too large. We did not ship it.
We assumed the lost answers were acids that now stopped at their salts. They mostly were not. Sorted by what was in the flask, more than half (55% at half strength, 42% at full) were acid chlorides reacting with an amine, with sodium hydroxide present to mop up the acid released, a standard way of making amides. In the lab the amine reacts faster than the hydroxide, so you get the amide. With the correction switched on, the engine let the hydroxide destroy the acid chloride instead, turning it into the very carboxylate the correction rewarded. Only 14–18% involved a free acid. And this group barely noticed the size of the correction (178 lost at full strength, 175 at half), which is why halving it helped everything except the ratio.
The lesson is about what a state can know. The correction was attached to the product, the carboxylate salt, so it rewarded reaching that salt by any road, including roads that never involved an acid. What decides the amide reaction is not which product sits lower but which reaction happens first, and Aufbau compares where reactions end up, not how fast they get there.
The two "missing" salts were never missing.
Trifluoroacetic acid and sulfuric acid looked worse than the rest: their sodium salts appeared nowhere in the engine's answer, so we recorded them as products the engine never proposes, a different gap needing different work. That was an instrument error. We had read only the winner and the runner-up. Listing every candidate showed both salts there, both at exactly 0.0, like all the rest. Something else simply scored higher: for trifluoroacetic acid, swapping a fluorine for hydroxide and forming sodium fluoride; for sulfuric acid, a loosely bound adduct.
The fluorines were priced correctly.
The obvious suspect for the fluoride answer was the single C–F value the engine uses for every C–F bond. Fluorines on one carbon do strengthen each other, but averaged over each molecule from measured heats of formation (taking each C–H at the engine's own value) the C–F bond runs 445 · 469 · 486 · 492 kJ/mol from CH₃F to CF₄, and the engine's 485 already is the CF₃ value. The reaction is genuinely downhill: CF₄ with water to CO₂ and HF releases about 70 kJ/mol. CF₃ groups survive sodium hydroxide because that reaction is slow, not because it is uphill. We added no correction.
- pKa
- a logarithmic measure of acid strength: each unit lower is ten times stronger. Acetic acid is about 4.8 and ethanol about 16, so the gap is roughly eleven units, or a factor of a hundred billion.
- candidate list
- every product mixture the engine proposes for a set of reactants before it chooses one. A product can be missing from the answer for two quite different reasons: never proposed, or proposed and outscored. Telling them apart means looking at the whole list.
- acid chloride
- a carboxylic acid with its –OH replaced by chlorine, which makes it very reactive. With an amine it gives an amide; with water or hydroxide it goes back to the acid. Which one wins depends on speed.
- averaged bond energy
- the total energy to pull a molecule apart into atoms, shared out over its bonds. It is not the same as the energy to break the first bond, and confusing the two was the mistake behind the fluorine diagnosis.
Two tools that would rather say nothing.
Both of these could be computed long before either had a screen. What made them worth building an interface for is not what they answer — it is what they decline to answer, and whether they tell you which case you are in.
Cluster Shapes runs Wade's rules forwards. A borane has fewer electron pairs than it has edges, so its shape cannot be found by drawing bonds; it is found by counting skeletal electrons. Give it B6H62− and it returns closo and an octahedron. Give it o-carborane and it returns closo and an icosahedron. Give it diborane and it refuses. There is no polyhedron with two vertices — two points make a line — and the rule assumes each vertex directs three orbitals at a cage interior that, here, does not exist. The arithmetic still produces a number, and you can see it on screen: four pairs against two vertices, which the rule's own table calls nido while convention calls diborane arachno. Nothing inside the arithmetic can settle that, because the arithmetic is the thing that broke. So the tool prints every figure it derived and declines only the classification.
Protecting Groups is the same shape of answer one level up. Put Boc on a molecule that carries its own tert-butyl ether and ask acid to take it off: the removal is run through the ordinary forward engine, and it comes back with nothing. The target's own bond is the bond the removal relies on, the two cleavages give the same formulas, and a winner that is barely ahead is treated as no winner at all. Put Cbz on the same molecule and it comes off, because hydrogenolysis does not touch that ether. Nothing in the engine was told that the two groups are orthogonal. It is the reason the second group exists, and it was discovered by running the first one and looking at what came back.
A refusal is a result, and it has a shape.
These two decline for different reasons, and the difference is worth keeping. The cluster refusal is a domain boundary — the rule has nothing to say about a two-vertex cage, and no amount of care with the numbers changes that. The deprotection refusal is a margin — the chemistry is in range, two paths compete, and the winner is not far enough ahead to call. The same word, "declined", covers both; the reasons do not transfer, and the screen says which one you are looking at.
We did not draw the cages we cannot place.
Five of the closed deltahedra have vertices that can be written down exactly. The others — the bisdisphenoid, the tricapped trigonal prism, the bicapped square antiprism, the edge-coalesced icosahedron — do not, so Aufbau names them and draws nothing. An approximate polyhedron sitting beside an exact electron count would be the one dishonest thing on the screen, and it would be dishonest in the most persuasive way available: a picture.
- closo, nido, arachno
- the three families of cage, distinguished by how many vertices are missing from the closed polyhedron they derive from: none, one, two. Which one applies follows from the electron count, not from the picture.
- deltahedron
- a polyhedron whose every face is a triangle. The cages boranes adopt are these, which is why "how many edges should it have" has an exact answer and can be used to check a drawing.
- protecting group
- a mask put on a reactive site so that chemistry can be done elsewhere, and taken off afterwards. It is only useful if it comes off cleanly — which is a claim about the specific molecule, not about the group.
- orthogonal
- of two protecting groups: removable by conditions that leave the other, and the rest of the molecule, alone. Usually taught as a property to memorise; here it is an outcome of running both removals and comparing what returns.
Right about ethane. Wrong about peroxide.
Rotating about a single bond costs energy, and how much of it decides which shape a molecule is actually found in. Everywhere else Aufbau answers that kind of question by reasoning about bonds. Here it does not reason about bonds at all — it solves the electronic structure at each angle and reads the total energy off the result. No force field, no torsional parameter, no barrier looked up.
Give it ethane and it returns a rotational barrier of 12.6 kJ/mol against a measured 12.1, with the staggered form lowest. That number comes out of integrals over Gaussian functions and nothing else. It is four per cent high, and high is the only direction it is allowed to be: the scan holds every other coordinate fixed, and letting the molecule relax at each angle can only lower a barrier, never raise it.
Give it hydrogen peroxide and it is wrong. The energy falls all the way to 180° — the molecule comes out flat — when the real minimum sits near 112°. This is not a subtle miss. It is the difference between a molecule with a handedness and one without.
The interesting part is why. The calculation gives every atom a small set of orbitals with fixed shapes — the cheapest description that is still quantum mechanics. Add richer ones, the kind that let an oxygen's electron cloud lean rather than only stretch, and the minimum moves to 112°. Peroxide's twist was never missing physics. It was a missing shape in the description, and the molecule cannot be twisted by a model that has no way to represent the twisting.
A tool that shows you its own limit.
The screen prints the measured minimum beside the computed one and says the basis is missing this when they disagree by more than a few degrees. That warning is not an apology; it is the feature. A conformational scan that quietly returned 180° for peroxide would be far more dangerous than one that returns 180° and tells you the description is too poor to know better — and the toggle that fixes it is right there, so the claim can be checked rather than believed.
We did not offer the molecules we cannot afford.
Cost grows as roughly the fourth power of the number of orbitals, and this is the real calculation rather than an approximation of it, so it costs what it costs. Butane would take minutes per point and is not offered at all. Richer orbitals cost about seventeen times more per point, so they are a switch rather than the default. Both numbers were measured before either decision was made, which is the opposite of the usual order.
- rotational barrier
- the energy cost of turning one end of a molecule relative to the other. Small — ethane's is about a fiftieth of the bond it turns about — and large enough to decide which shape you actually find.
- basis set
- the fixed collection of orbital shapes a calculation is allowed to build its answer from. A poor one is not a rounding error: there are answers it cannot express at all, and peroxide's twist is one of them.
- rigid scan
- turning the angle of interest while holding everything else still. Cheaper than letting the rest relax, and it makes every barrier an upper bound — which is a caveat worth stating, because the number looks the same either way.
- upper bound
- a value the true answer cannot exceed. Useful precisely because it is one-sided: a rigid barrier that comes out too low would mean something is wrong, while one that comes out high may simply be rigid.
Deterministic computer-aided molecular design.
Computer-aided molecular design has two established species. One retrieves: a database of structures and measurements, which can only answer for what somebody already recorded. The other predicts: a model trained on that database, which answers for anything you ask and cannot tell you when it is guessing. Aufbau is neither. Sculpt, new in 1.9, is the first piece of a third kind — a design surface where every answer is computed from the same energy model that builds the molecule, and where asking the same question twice gives the same answer to the last bit.
Add a virtual charge group to an atom and the bonds bend away from it, the way a real lone pair or substituent would. State what you need — this angle at 109.5°, these two atoms 2.4 Å apart, that torsion anti — and Sculpt drives the geometry toward it. Then it reports the miss. Where a target fights the chemistry, the chemistry wins and the tool says so, in ångströms and degrees. That is the difference between a design tool and a drawing program: you can ask for anything, and it will tell you what it costs.
The companion tool, Why Molecules Bend, strips the idea to its floor: put N things on a sphere, let them push each other apart, read off where the bonds point. No hybridization, no sp³. Hold four domains and step the lone pairs, and three familiar molecules appear from one calculation —
| Molecule | Bonding | Lone pairs | Computed | Measured |
|---|---|---|---|---|
| Methane | 4 | 0 | 109.5° | 109.5° |
| Ammonia | 3 | 1 | 106.2° | 107° |
| Water | 2 | 2 | 103.5° | 104.5° |
Same sphere, same solve, one number changed. And the one empirical constant in that account — how much harder a lone pair pushes than a bond — is exposed as a slider rather than buried. Set it to 1.00 and water opens back out to a clean tetrahedron. Being able to switch off the cause and watch the effect vanish is a stronger argument than any diagram of it, and it is something the hybridization story cannot offer, because it never named a cause to switch off.
Sculpt measures the geometry you pose. It does not predict the shape a ligand prefers — no ideal cavity size, no matched pocket. We tried, six times, against crown ethers whose cavities crystallography already settled, and every attempt failed a test written before it ran. So the tool declines rather than guesses: ask it for the hole in a structure whose donors are not really surrounding a point, or one whose bonds have been stretched to reach a target, and it tells you that instead of quoting a number. An instrument that refuses to read is worth more than one that always answers.
Four decades ago LHASA asked which reactions could build a molecule. This asks what shape
it has to have — the other half of the same ambition, on physics the 1980s could not compute. Deterministic
throughout: identical input, identical geometry, content-addressable. Reproducible from the shipping build:
echo '{"op":"geometry","smiles":"O"}' | aufbau-engine --serve
The engine keeps growing — in public.
Aufbau didn't arrive finished. Each release widened what the same first-principles engine can derive, and the benchmark above tracks it honestly as it grows.
Bonding & structure, from atoms
Molecules build by energy minimization — covalent, ionic, metallic, and coordinate bonds all emergent; aromaticity by the Hückel rule; real 3-D geometry you can rotate.
Reaction prediction from first principles
Enter reactants and the engine computes the products from bond energetics — with an honest verdict, and an honest “no reaction” when nothing favorable exists. No lookup.
Multi-step routes & a new family of chemistry
The step-by-step pathway to a product, each step's mechanism and energy — including urea from captured CO₂ and ammonia, the real industrial route, derived end to end. Plus portable, self-verifying share codes.
Find the missing reactant
Turn the question around: mark a reactant as a wildcard, name your target, and Aufbau reasons backward to the reagent you need — and names it even when it isn't on your shelf, turning “no” into “here's what to get.”
A bug found and fixed, in public
The engine keeps getting more faithful. We found and fixed a real bug in the computed periodic table: for heavy elements the electron configuration came out wrong — Oganesson (element 118) had a spurious orbital instead of its true [Rn] 5f14 6d10 7s2 7p6. Fixed with a regression test and shipped in 1.3.1. That's the quiet advantage of computing instead of storing: when it's wrong, the mistake is a specific, findable, fixable line — not a mystery inside a trained model.
Reactions judged by ΔG, not bonds alone
The gate now weighs entropy as well as bond strength — ΔG = ΔH − T·ΔS — so a reaction driven by a small gas molecule escaping can turn favorable above a crossover temperature. Aufbau derives ethanol → ethylene + water on its own, reproduces the Haber trade-off (ammonia synthesis reversing when heated), and still holds every negative control inert. The benchmark moves to 48 of 49.
The catalyst, from the configuration
The boundary the free-energy layer stopped at — catalytic control — is now crossed, and crossed the honest way: a metal's catalytic character is derived from its electron configuration, not looked up. Copper's filled d¹⁰ shell selects acetaldehyde from ethanol; iron's open d-shell enables ammonia by dissociating N₂ (which otherwise won't react). The benchmark reaches 49 of 49. A real configuration bug — the anomalous d¹⁰ ground states — was fixed on the way. See the field note above.
Handedness, assigned from the graph
The engine now sees three-dimensional chirality — R/S at carbon and even at a sulfoxide's sulfur, E/Z across double bonds — derived by the CIP rules from the molecular graph, and shown with the correct handedness in 3-D.
Why the Diels–Alder goes
Pericyclic selectivity — the Woodward–Hoffmann rules — read straight off the frontier molecular orbitals: the classic cycloaddition allowed, the [2+2] forbidden, and both inverting under light, because the orbitals do. The phases are drawn as coloured lobes.
Designing a rare-earth separation
The frontier orbitals reach past molecules to metals: which ligand donor grabs which ion (hard–soft matching plus the ligand field), and a full plan for pulling a rare-earth mixture apart — strip the redox-separable ones, chelate the rest. See the field note above. Patent pending.
Sculpt — push back on the geometry
The first piece of deterministic computer-aided molecular design: state the shape you need and the engine reports what the chemistry says it costs. A companion tool derives the shape rule itself from domains on a sphere — methane, ammonia and water from one calculation, no hybridization. And it declines to answer where the geometry cannot support an answer.
The benchmark also went 48 of 49 → 46 of 49 in this release, and the engine did not change. Two rows were being scored on the product formula, which cannot tell isomers apart; scored on structure, both fail — the engine returns butanoic acid where an ester belongs, and 1,1-dichloroethane where the 1,2- belongs. A third row is a correct refusal. The number is lower because the scorer can now see things it could not see before.
Checked against measurement, and the answer written down
The engine's answers had been scored for a year; its arithmetic never had. So we compared it reaction by reaction against published enthalpies, derived standard entropy from first principles instead of a lookup table, measured where the nuclear model is trustworthy, and confirmed the stereochemical descriptors by hand from the CIP rules. Most of it came out very close. Two enthalpy errors did not, and both are now pinned at their exact size in the test suite rather than rounded away. The pass also caught things the benchmark could not see: products that changed depending on the order you typed the reactants, elements outside the engine's data being quietly substituted rather than declined, and a share code that dropped a molecule's handedness while reporting itself verified.
The base is not a switch
An aldol makes a carbon–carbon bond, and the engine had always refused to form one — deliberately, because nothing stopped it welding two skeletons together into molecules the reactants cannot reach. So the aldol was never enumerated, not rejected on energy. A Brønsted base is what removes the α-hydrogen, and therefore what makes that bond reachable at all; asserting one licenses the move and nothing else. The same release derived which way an alkene adds — Markovnikov’s rule falling out of the energies rather than being written down.
Working backwards, and only keeping what it can reverse
Ask for a target and the engine disconnects a strategic bond, caps both freed valences so the pieces are real molecules rather than radicals, and keeps the cut only if the forward model rebuilds the target from them. There is no transform library: nothing in the file knows what an ester is, and the three caps — H, OH, Cl — are simply the ways a dangling valence can be satisfied. Which one applies is the forward engine’s answer, not a rule. Aspirin comes apart into salicylic acid and acetic acid; Vitamin C opens its own ring.
A curriculum, and the group that gets in the way on purpose
Lessons that derive rather than assert: molecular shape from points repelling on a sphere — methane, ammonia and water from one calculation, with hybridization never mentioned — and lessons that work through why a mixture will not simply react, and how to plan a route backwards. Everything the lesson claims is computed live by the same engine that answers everywhere else. No language model is involved.
Alongside them, the piece of classical synthesis planning that has been missing: protecting groups. The engine now notices, on its own, that a step it wants would attack the wrong site — the fragments do react, they simply build the wrong molecule — and answers by masking the competing site, coupling, and taking the mask off again. It also declines a protecting group whose removal would destroy the product, and reaches for a second one that survives. That decision is made by running the removal and reading the result, not by a table of which group suits which case.
Underneath both, a correction to how bonds are priced. A bond is not worth the same everywhere: an ester oxygen is not an ether oxygen, and a benzylic bond is not an ordinary one. Two long-recorded errors in the engine’s reaction enthalpies were halved by saying so once, and a defect nobody was hunting fell out with them — chlorinating benzene had been destroying the aromatic ring instead of substituting into it.
A screenshot found what the tests did not
The blue clouds above and below an aromatic ring are what make it read as benzene rather than a hexagon of lines. They existed in one view. They now appear wherever a molecule is drawn in three dimensions — including Sculpt, where the shape is worked out from scratch and a ring can end up at any angle, so each cloud is fitted to its ring’s own plane rather than assuming the ring lies flat.
Switching them on everywhere is how porphine’s drawing was found to be wrong: four huge overlapping annuli laid across the molecule, two small clouds, and two rings with nothing on them at all. The renderer had been handed six rings — sizes 5, 5, 16, 17, 17, 18 — four of which were one delocalised circuit counted four different ways round. The filter dropped a ring only when a smaller ring was a subset of its atoms, which is true of naphthalene and false the moment a perimeter takes a shortcut: porphine’s macrocycle threads each pyrrole by its nitrogen and two α-carbons and skips the β-carbons, so no pyrrole was a subset and nothing was dropped. The right question is not whether a ring sits inside another but whether it says anything the smaller ones did not — cycle independence — and asked that way porphine gives [5, 5, 16]: one annulus threading all four nitrogens, plus the two pyrroles that are aromatic on their own. Naphthalene’s perimeter still drops, now for the better reason.
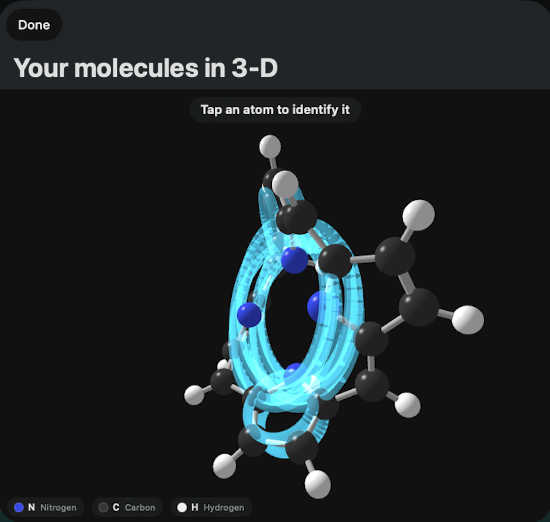 before — six rings, [5, 5, 16, 17, 17, 18]
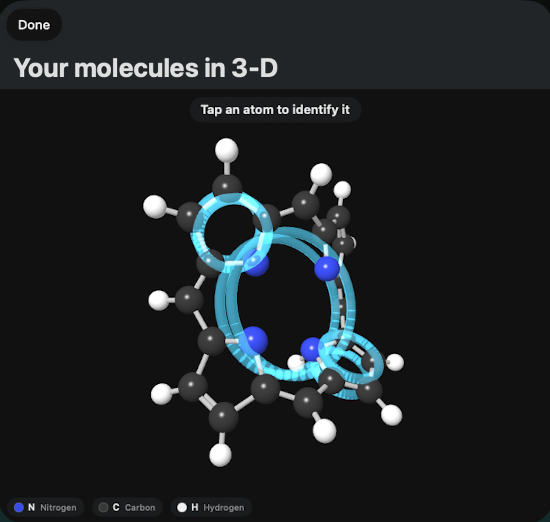 after — three rings, [5, 5, 16]
Worth being exact about what was broken, because it would be easy to claim more: the chemistry never moved. The reactor reads the full circuit list for its delocalisation energy and always did. Only the set chosen for drawing was wrong — and it survived a month because that filter had no test of its own, while the function it filters had plenty. It was caught while capturing a screenshot for the App Store, which is a poor substitute for a test and was, that day, the only thing looking.
A smaller change that matters more than it sounds: a route now names what it wants. The leaves of a retrosynthesis were bare formulas — C7H6O3 — which is not an answer you can take to a supplier. They now carry the reagent’s name beside its formula, and a fragment you can simply buy no longer has that fact hidden behind a badge telling you it is aromatic.
Six things that had shipped, and stayed shipped
Aufbau’s windows could not be resized. Not by dragging a corner, not by the Window
menu’s own Fill command, not by the accessibility API — every window opened at 924 by
694 points and stayed there, whatever display it was on. Mac Catalyst caps each window through
UIWindowScene.sizeRestrictions, and the lift for it hung off a zero-sized view whose
appearance callback never fired, on a screen it was never attached to. It is lifted at the scene
level now, so it depends on no view being drawn.
The same ceiling was quietly shrinking every panel that opens on top of a window. The molecule viewer asked for a thousand points of width and was given about five hundred and fifty, so porphine — thirty-eight atoms — was drawn into a fifth of the window it sat in. On a 1080p display the Reactor was worse: its spontaneity and kinetics readings sat below the bottom edge and could not be scrolled to. Both now use the window they are in.
Then a crash, which is the one that mattered. Asking for a route to a target made of more than one piece — an ionic reagent, a typed mixture, a saved reaction recalled from the library — could quit the app outright. The planner asked whether the molecule had come apart in two when the question it needed was whether the bond it had just broken was the thing that separated them. For a connected molecule those are the same question. For a mixture with a ring in it they are not, and it reached for an atom that was not there.
One computed result moved. Building a porphyrin from pyrrole and formaldehyde ended in an oxidation that took the ring too far, pulling hydrogen from all four nitrogens to give C20H12N4 — where porphine is C20H14N4 and keeps two N–H. The macrocycle was always right; only the last step overshot. Oxidation now stops when the ring becomes aromatic, which is what drives it, rather than continuing while a wider circuit can still be traced. This page already said porphine carries two NH pyrroles: the site was right and the engine was wrong.
Two smaller corrections, both about not overclaiming. A finished route used to hand back HCl where the reagent shelf beside it says hydrochloric acid — two catalogues of the same idea that had never been introduced, and which disagree on notation, the shelf writing H2SO4 where the engine writes H2O4S. And a leaf the planner merely stopped at because it was small no longer calls itself a building block: hydrogen thioperoxide is a transient, not something to order.
None of this was found by the test suite, which passed throughout. Every one of them was found by looking — at a window that would not grow, at a route that named nothing, at a crash report. The checks that should have caught them existed and were not wired to a verdict: the release script could not fail on a red suite, and the porphyrin synthesis was demonstrated by a debug-only routine that merely printed. Both now report. That is the more useful half of this release.
A textbook ordering, computed — and three bugs found on the way to it
Put six ligands around a transition metal and its five d orbitals stop being equal. The size of the gap between them decides a compound’s colour, its magnetism and much of its reactivity, and ranking ligands by it gives the spectrochemical series — one of the oldest orderings in inorganic chemistry, and for a century something you looked up. Aufbau now computes it: Tools ▸ Ligand Field builds six octahedral complexes, places each ligand at the sum of the covalent radii, solves them, and ranks the ligands by the splitting that falls out. For the early transition metals six of the nine come out in the correct order, including the whole weak-field end — with nothing in that path fitted to the answer, and the series never given to the engine.
Copper manages three, and the screen says so beside the six. Scandium’s d level sits above every ligand level, which the model handles; copper’s sits below most of them and the interaction inverts. The real series is very nearly the same for every metal, so that drop across one row is a genuine limitation rather than a caveat, and it is displayed rather than described. Back-bonding falls out of the same calculation: carbon monoxide takes electron density back into an empty orbital of its own, and nothing was added to the model to make it — that orbital is simply one of CO’s. A bare atom, which has none, reports exactly zero.
Three corrections underneath reach far past this screen. Valence orbitals for the heavier elements had been built with the shape belonging to the second row, leaving iodine’s outer shell about four times too compact — every element from sodium down was affected. The transition metals’ orbital energies were derived where a measured table exists, with roughly two and a half times the correct slope across the row. And six of the nine first-row metals had no covalent radius at all, so they could not be placed in a structure. Before any of that, four rounds of work went into diagnosing an elaborate physics defect — smeared orbital character, antibonding levels at +83 eV — that turned out to be a unit conversion: the solver takes atomic units and was being handed ångströms, so every complex had been built at 53% of its intended size. One check of a two-centre overlap against its exact closed form, which needs no reference data at all, would have caught it four rounds earlier. The benchmark is unchanged at 49 of 49.
Wider chemistry, same honesty
The catalyst archetypes reach further than the two effects wired so far — hydrogenation and oxidation are characterised and waiting. Beyond that: broader, functionally dense organic chemistry through principled corrections, the deeper configuration anomalies that need real orbital energies, and independent large-scale testing — measured on reproducibility and fabrication rate, the axes that matter.
We ran 153,237 published reactions cold. Aufbau got 19.77% of them exactly right — molecule for molecule.
Every number on this page so far is one we chose to measure. A benchmark we assembled, molecules we picked, misses we went looking for. The obvious objection is the obvious one: you graded your own homework.
So we took the Open Reaction Database — 2,428,070 reactions published by other people for other reasons — and ran the engine against it cold. Nothing in Aufbau was fitted to it; nothing in it is consulted at runtime. It is not training data and could not be: the engine has no trained anything. Every one of those reactions is out‑of‑sample by construction, which is a sentence no fitted model can write about the literature, because for a fitted model the literature is the sample.
What we could even ask. Of 2,428,070 reactions, 1,775,687 use only elements the engine knows — and just 623,744 of those also fit under twenty heavy atoms, which is where the calculation is affordable. Require a recorded temperature and 153,237 remain: 6.3% of the corpus. That funnel is itself a result. We had assumed element coverage was the constraint; it is not. The median published reaction’s largest molecule has 24 heavy atoms, and size is what excludes most of chemistry from us today.
The first answer was 7.9%, and it needs its qualifications stated before anyone asks for them. Matching is at formula level, which means an isomer counts as a hit; the true structure-level figure is lower. The run is enthalpy-only, which is what makes 153,237 reactions affordable at all and also what keeps a seventh of them at “no reaction”.
Then the measurement caught us. Sorting every disagreement by what the literature said had left the molecule produced one cluster far larger than the rest: water. Condensation — two molecules joining while water leaves — accounted for about 11% of everything we could ask, more than the next four categories combined. We published that as the next thing to build.
It was not missing chemistry. The engine has been able to model a condensation driven by water removal since the Le Chatelier work landed — and the command-line interface never exposed the argument that says the water is being taken out. So every batch measurement we had ever run, including the one we had just published, judged esterification with the water still in the flask, where the equilibrium sits nowhere and a correct engine refuses. One flag, never wired up:
| 20,833 water‑loss reactions | as first measured | with water removal |
|---|---|---|
| exact | 6,628 31.8% | 19,232 92.3% |
| wrong products | 11,297 54.2% | 1,134 5.4% |
| no reaction | 2,908 14.0% | 467 2.2% |
Across all 153,237, agreement went from 7.9% to 17.6%, and on condensations themselves from 31.8% to 92.3%. One argument, reachable from a shell for the first time, more than doubled the whole result. It is not a flattering story and it is the reason the harness exists: we would never have found it by reading our own code, because we had read our own code and concluded the chemistry was missing.
It has moved once more since, to 17.8%. Those figures — 7.9% to 17.6% — are what the water argument alone was worth, and we have left them as they were rather than quietly restate them. The rest came from one missing bond‑energy value. Alkylating a deprotonated sulfonamide is ordinary chemistry and the engine called it inert, as it did for every nitrogen bonded to sulfur; it had found the right answer each time and discarded it, because the potassium could move somewhere it should not and the resulting arrangement scored higher. Tabulating that one bond took the 16,208 reactions of that kind from 2.97% to 4.32%. Three other changes were built and measured in the same pass and all three made the total worse, so they were reverted — they cut wrong answers and turned them into silence, which is not the same as being right.
What survives is the real gap. 1,134 reactions still come out wrong with water removal switched on — the engine reaches for the reaction, and builds the wrong thing. That is condensation the engine genuinely cannot do yet, no longer confounded with condensation it was never told to attempt. Halide substitution is now the larger cluster — bromide at 3,391, chloride at 1,952 — and both are far better‑defined targets than “condensation” was a day ago.
And then it caught us a second time. The figures above were first published as 9.8% overall and 9,357 surviving failures. Both were wrong, and wrong in our own disfavour: the harness compared formula strings it built in one element order against the engine’s, which uses another. Anything containing a halogen next to a nitrogen — C8H7NOFCl against C8H7ClFNO — could never match, however right the engine was. About twelve thousand correct answers were being scored as failures. The engine never changed; only the scoring did.
And then it caught us a third time — in our favour, which is worse. Every figure above matches formulas. We said so when we first published it: an isomer counts as a hit, so the true structure‑level figure is lower. We had not measured how much lower. Now we have. We re‑ran all 153,237 reactions on the current engine, with the same settings as every figure above — water removal only, which is how the engine ships — kept the structure of every product, and checked each answer molecule by molecule rather than formula by formula.
| All 153,237 reactions, current engine, water removal only | exactly right |
|---|---|
| matched by formula — how every earlier figure here was scored | 27,928 18.2% |
| matched by structure — the molecule the paper made | 21,762 14.2% |
More than one formula match in five — 6,166 reactions — was the wrong molecule with the right atoms: an isomer, a group added across the wrong bond, a product that happened to weigh the same. The first two measurement errors on this page hid right answers; this one invented them. It is the more dangerous kind, because nothing about it looks wrong. It surfaced while we were checking a fix: of 34 answers it appeared to win and lose, 24 were formula coincidences, and every one of its apparent losses was one. So 14.2% is the number we then stood behind — 14.3% after the rule described in the field note below, and 14.6% since the engine learned to finish what a deprotonation starts: when one step leaves a freshly made nucleophile beside an untouched partner, it takes the second step the literature reports (+385 right answers, −6). It was 14.9% after two more, and 15.1% when Aufbau 1.27 shipped. It was 19.2% when 1.28 shipped (field note) and is 19.77% now; the 1.29 field note takes the last steps one at a time. The engine could not form a new carbon–carbon bond at all — 25,695 of these reactions must make one, and it had exactly one right — until it learned the organometallic addition: a carbon–metal bond adding across a carbonyl, stated as a property of the atoms. And it now reports each reaction’s products as they are isolated, after the aqueous workup that every paper performs before it records a product, rather than as the metal salts that sit in the flask. That second change is a choice about what is compared, so it is stated here: without it, the same engine scores 14.9%, and its new carbon–carbon answers (268 right) are not counted at all, because they are still sitting as metal salts. The last step to 15.1% was bookkeeping the engine had wrong: it read a nitro group — a nitrogen carrying a positive charge beside an oxygen carrying a negative one — as a nitrogen with one bond too many, and that one “allowed” violation let impossible products through elsewhere. Recognising the charge‑separated pair from the atoms themselves gained 372 right answers and lost 3. It is deliberately strict: it ignores stereochemistry, but a correct product written as a salt instead of its free base still counts as a miss, and so does a “product” that is just a starting material handed back unchanged.
What this does not claim. 19.2% is measured on 6.3% of a corpus, with water removed and products reported after aqueous workup (18.95% without the workup), judged on structure, one step at a time (two only where a deprotonation leaves a nucleophile beside its partner, or a ring closes straight after the bond that sets it up), without a free‑energy gate apart from the entropy of water a heated reaction drives off. It decides which products are energetically allowed, not how fast competing reactions run, so it has no notion of concentration: concentration only matters once we model rates (effective molarity against reagent concentration), and the engine doesn’t do that yet. It is not an accuracy score and we are not offering it as one. It is the first honest measurement of how far a first‑principles engine gets on chemistry it did not choose — and the direction of the work now comes from that table rather than from our taste. When it disagreed with us, we moved: reagent vocabulary looked like the obvious next brick, and three runs showed that supplying reagents correctly changed the result by nothing at all.
Some bonds have nothing left to give. We stopped offering them.
Aufbau ranks reactions by energy: whatever sits lowest wins. That is right about where chemistry ends up and silent about how fast it gets there — and a bond can be thermodynamically fair game and still never react in a flask. A CF3 group next to sodium hydroxide is the clean case: trading a C–F for a C–O and sodium fluoride really is downhill, and CF3 groups survive sodium hydroxide anyway. The engine kept making that trade.
The fix is one idea: some parts of a molecule have achieved nobility, and should not be offered to a reaction at all. The work was turning that into something the engine could decide from the atoms themselves rather than from a list of groups. The version we settled on is this: a bond is noble when neither end offers an incoming reagent anything to take hold of — no lone pair to donate, no empty orbital to accept, no π bond to attack, no group ready to leave.
Three kinds, each a property of the atoms.
Spectator cations. A sodium, potassium, lithium or magnesium ion already in a salt has a noble‑gas electron configuration. It may change partners — hydrochloric acid and sodium hydroxide still make sodium chloride — but it never forms a new bond to carbon, phosphorus or sulfur.
Saturated carbon with nothing attached. A carbon with four single bonds to carbon, hydrogen or fluorine has no handle: its C–F bonds are noble, and so are its C–H bonds unless they sit next to a π system.
Dinitrogen. N2 in the flask is an inert atmosphere.
Anything a reagent can use.
Halide anions have noble‑gas configurations too, but they are good nucleophiles — iodide displacing chloride is everyday chemistry. CO2 is small and stable, but its polarised double bonds are a handle, and CO2 plus ammonia is the urea route on our own home page. A C–H next to a carbonyl is the acidic one. C–Cl, C–Br, C–I, every π bond and every lone pair stay available.
The definition was rewritten three times while it was being built, all before any measurement: once because a test caught the first wording excluding the very CF3 that motivated it, and twice because it contradicted chemistry we already rely on — halide exchange, and CO2 with ammonia.
Then we measured it on the same 153,237 published reactions, the same engine with the rule switched off and on, graded molecule by molecule:
| 153,237 reactions, one engine | rule off | rule on |
|---|---|---|
| exactly right, by structure | 21,762 14.20% | 21,966 14.33% |
| right answers gained / lost | — | +211 / −7 |
| wrong answers that became an honest “no reaction” | — | 854 |
| “no reaction” that became a wrong answer | — | 238 |
| reactions whose answer did not change at all | — | 146,717 |
Thirty right answers gained for every one lost, and more than six hundred confident wrong answers net turned into declines — while 96% of the corpus came out identical, which is what a rule about spectators should do. It is on by default now. With it switched off the engine reproduces its previous answers byte for byte, which is how we know the table measures the rule and nothing else.
Put enough energy into a flask and even a noble bond reacts — the noble gases themselves form compounds under forcing enough conditions. So the rule now has a temperature in it. Nobility holds for polar chemistry; it lifts once radical chemistry becomes possible, and that happens when the weakest bond in the flask can break on its own within the time an experiment takes. For one bond breaking, the rate is k = A·e−D/RT, so the onset is
T* = Dweakest / (R·ln(A / k10 h))
with A = 1016 s−1 — the measured range for a single bond breaking — and k10 h the rate that gives a ten‑hour half‑life, which is how the companies that sell radical initiators define “active”. Nothing in it was fitted.
We checked it against those companies’ own published data before building anything. For peroxides that come apart by one bond breaking, it lands 8–18 °C too hot — di‑tert‑butyl peroxide at 137 °C against a published 121–129 °C — which errs toward keeping nobility on. It fails for initiators that fall apart by ejecting CO2 or N2 in one concerted step, such as lauroyl peroxide and AIBN, because for them the bond energy is not the barrier. We did not adjust the constant to hide either.
The first build then caught us out. It took “weakest bond” from the engine’s own bond table — a table of averaged energies for pricing whole molecules, some of them deliberate pricing devices, such as a carbon–lithium value set low so an organolithium never looks like a stable product. Read as the energy to break one bond, those values would have switched nobility off in about 3,470 of the 3,660 published reactions the rule flagged, for no chemical reason. We caught that before it was measured, let alone shipped. The onset now uses measured bond‑breaking energies (from the CRC Handbook) for the bonds that set it — peroxides, hydrazines, disulfides, the halogens — leaves out ionic and metal bonds, and ignores bonds with no measured value, which keeps nobility on.
On the 153,237 published reactions, each run at its recorded temperature, it changed the engine’s output for exactly eight, and all eight are radical conditions by any chemist’s standard: bromine, iodine or a peroxide, well above their onset. Propane and bromine at 270 °C now brominates — textbook free‑radical halogenation, though to the 1‑bromo rather than the 2‑bromo product the literature reports, which is a separate question about where on a molecule a reaction happens. Right answers gained and lost: zero and zero. That is what a correct rule about temperature should do to chemistry that was run near room temperature.
Rings in one move, a rule about speed, isotopes — and the same bits everywhere.
Three things changed between 1.28 and 1.29. The engine learned several ring‑forming reactions that change too many bonds at once for its smaller moves to reach. It learned one rule about rates, which a purely thermodynamic engine does not otherwise have. And it learned isotopes, and to give the same answer to the last bit on any machine. As before, every step was written down before it was built and measured on the same 153,237 published reactions with the change switched off and on.
| Since 1.28, in the order it landed | right answers gained / lost | exactly right after |
|---|---|---|
| Aufbau 1.28, as shipped | — | 29,427 19.20% |
| A slow ring closure is a last resort: four‑membered rings, rings of eight or more, and most three‑membered rings form only when nothing else reacts | +171 / −17 | 29,581 19.30% |
| Knoevenagel condensation in one move (an active methylene meets an aldehyde or ketone) | +108 / −0 | 29,689 19.37% |
| Doebner: no direct amide from a free acid without an activator; CO2 credited only where a carboxyl actually leaves | +219 / −7 | 29,901 19.51% |
| Azides add across nitriles and alkynes: tetrazoles and 1,2,3‑triazoles | +126 / −0 | 30,027 19.60% |
| Hydrazones that finish the ring: pyrazoles, aminopyrazoles, indazoles | +251 / −1 | 30,277 19.76% |
| Activated aryl fluorides and chlorides close without added base | +17 / −0 | 30,294 19.77% |
That is 892 right answers gained and 25 lost — about thirty‑six for every one. The azide, hydrazone and activated‑halide steps each include a refinement designed after a first run was seen, so those measurements are in‑sample and we say so. Some arms failed and were not shipped: a combined Knoevenagel rule lost more than it gained until the generator was measured alone; a first azide version cycloadded azide‑transfer reagents it should have left alone; and a chromone ring‑closure rule gained 1 and lost 5, all on one reaction listed five times. Each is in the record with the run that settled it.
Slow rings wait their turn.
An energy‑only engine will close any ring that is downhill. Chemists know some rings are slow to close: the two ends of a chain rarely meet when the ring would have four members, or eight or more. When the engine’s best answer is one of those closures, it now looks again without it, and reports the slow closure only if nothing else reacts. It is a single, stated rule about ring size — the first place the engine says anything about how fast, not just how far.
Labels that stay where you put them.
A deuterium label rides on its atom, so CH2D–OH and CH3–OD are different molecules to the engine and the same molecule to the chemistry. Masses come from the 2020 Atomic Mass Evaluation. Against NIST and JANAF: harmonic HD/H2 and D2/H2 ratios −0.03% and −0.07%; entropy shifts within 0.11 J/(mol·K); both H/D exchange equilibria within 0.09 kJ/mol from 298 to 1000 K. On the 336 corpus reactions that carry a label, every answer is byte‑for‑byte unchanged — labels add information without moving results.
Checking the nuclear side against the same evaluation found two errors of our own: a hand‑entered platinum‑197 value 4.85 MeV off, and a β‑decay formula missing 0.782 MeV. Both are fixed, and binding energies now come from measurement wherever a nucleus has been measured.
Earlier on this page we reported that Apple silicon and Intel gave the same chemistry with different last digits. 1.29 closes that. The engine now carries its own correctly‑rounded math library (CORE‑MATH, MIT licence) and does its vector arithmetic in a fixed order, so nothing depends on the platform’s own math. The first attempt failed — Apple builds still differed — and the failure is what showed that the vector library was a second source of difference. After the fix, samples of thousands of reactions and molecules matched bit for bit on every machine we run it on, including Linux and two generations of Raspberry Pi, and the whole corpus of 153,237 gave identical verdicts on a Raspberry Pi 4 and the Mac; about 24 million checks of the math against multiprecision arithmetic found no genuine mismatch. It costs 3% at 0 K and 8.4% at 298 K.
The engine reads the flask. 15.1% became 19.2% in eight days.
Until 1.28 the engine priced a reaction as if the reactants sat alone. A published reaction says more than that: an acid, a coupling agent, a reductant, a base, a temperature. A chemist reads that list before deciding what will happen; the engine ignored it. Most of the change since 1.27 is the engine learning to read it — from the atoms of what is in the flask, not from a list of reaction names — and the rest is prices it had simply had wrong.
Every step below was written down before it was built, measured on the same 153,237 published reactions with the change switched off and on, and kept only if it gained more than it lost by at least five to one. Switched off, each reproduces the previous engine’s answers exactly.
| Since 1.27, in the order it landed | right answers gained / lost | exactly right after |
|---|---|---|
| Aufbau 1.27, as shipped | — | 23,140 15.10% |
| Carbonate bases: a spectator that still takes a proton, and an exact search over what carbonate chemistry can make | +3,064 / −70 | 26,134 17.05% |
| Hypervalent sulfur no longer over‑credited (measured, 107 kJ/mol per extra pair) | +312 / −1 | 26,445 17.26% |
| Rings that cannot exist: strain for flat atoms in three‑membered rings; no short bridge across a benzene ring | +522 / −6 | 26,961 17.59% |
| Conditions: acids, activators and reductants recognised from their atoms | +813 / −109 | 27,665 18.05% |
| Aromatic rings priced from measurement (13 ring classes) | +563 / −110 | 28,118 18.35% |
| Carbonyl condensation in one move: imines, oximes, hydrazones, ring closures | +233 / −13 | 28,338 18.49% |
| Water a heated reaction drives off, credited at the recorded temperature | +404 / −79 | 28,663 18.71% |
| N–O bonds break only with a reductant | +559 / −18 | 29,204 19.06% |
| Hantzsch thiazoles: sulfur alkylates first, then the ring closes | +195 / −0 | 29,399 19.19% |
| Thiazole’s own aromatic value, anchored through benzothiazole | +28 / −0 | 29,427 19.20% |
That is 6,693 right answers gained and 406 lost — about sixteen for every one — on reactions the engine was never fitted to. Without the aqueous workup the same engine scores 18.95%.
Roles, from atoms.
An alcohol’s OH is a poor leaving group, and in most flasks it stays put. It leaves when something activates it: a strong acid, a sulfonyl chloride, a phosphorus reagent, the Mitsunobu pair, an amide acetal. The engine now classifies everything listed with a reaction into those roles by looking at its atoms — a sulfur double‑bonded to two oxygens and carrying a chlorine is a sulfonyl activator whatever it is called — and lets the OH leave only when one is present. An N–O single bond is the same story with a reductant: oximes and hydroxylamines keep it in ordinary chemistry and lose it under hydrogen or zinc.
This extends the nobility rule from 1.27: a bond that has nothing to offer a reagent is not offered to a reaction, and now the flask can change what counts as “nothing”.
Aromatic rings, measured.
We compared the engine’s energy for aromatic molecules with their measured heats of formation (NIST). Every aromatic ring came out under‑priced, by an amount that depends on the kind of ring and transfers from one molecule of that kind to the next: about 164 kJ/mol for a benzene ring, 98 for pyridine, 80 for furan, 114 for thiophene — and 330 for a tetrazole. Thirteen ring classes now carry their measured value; a class with no measurement (isothiazole, for one) gets none rather than a guess. Thiazole had no direct measurement, so its value comes from benzothiazole and was checked against 4‑methylthiazole.
Priced correctly, the engine stops tearing rings apart to make something it thought was lower in energy — which is why this step also turned 9,583 wrong answers into “no reaction”.
A condensation — an amine or hydrazine joining a carbonyl while water leaves — changes four bonds at once, more than the engine’s two‑bond exchanges can reach. It is now one move, including a ring that closes immediately afterwards (a 1,3‑diketone and hydrazine give a pyrazole). The Hantzsch thiazole synthesis was invisible for the same reason: the first step, sulfur attacking the alkyl halide, rearranges six bond orders together. Of 424 published reactions that make a thiazole this way the engine had none right; the new move alone brought that to 180.
Heated reactions that drive off water now get credit for it: each water molecule released is worth its gas‑phase entropy, 188.84 J/(mol·K), times the temperature the paper reports. That is a textbook number, not a fitted one, and it is applied only where the water is being removed.
Across these steps 12,859 wrong answers became an honest “no reaction”, and 3,788 reactions went the other way — from “no reaction” to a wrong answer. The water credit alone moved 655 that way: once water counts, the engine commits to condensations it used to decline, and some of them are the wrong condensation. Two refinements were designed after we saw a first run’s losses — the rule that lets a condensation yield to a faster amine reaction, and the exemption that kept the N–O rule from blocking nitration — so their measurements are in‑sample, and we say so.
Some ideas failed and were reverted rather than shipped. Requiring an acid before an alcohol or amine adds to an ordinary C=C gained 6 and lost 9. Running the exact search on every reaction made things worse, 75 gained against 324 lost on a ten‑thousand‑reaction sample, because the exact lowest‑energy arrangement is where chemistry could end up, not where a flask stops. Blocking intramolecular ring closures for acids gained 55 and lost 66. Each is in the record with the run that killed it.
Honest limits, and where we're headed.
Aufbau is an interpretable model — it makes mechanism visible and derivable — not a research-grade quantitative predictor, and it says so. It's strongest on small-molecule, main-group, and inorganic reasoning; functionally dense, selectivity-driven organic chemistry is the frontier, and where expert chemical knowledge remains irreplaceable. The free-energy layer closed the entropy-driven gap, and config-derived catalysis just crossed the boundary it stopped at — copper selects, iron enables, both from the periodic table. What's ahead: wiring the catalyst archetypes that are characterised but not yet gate-active (hydrogenation, oxidation), broader organic coverage through principled corrections, and independent large-scale testing against database and machine-learned baselines, measured on reproducibility and fabrication rate — the axes that matter for trustworthy tools.